 MySQL Integration Guide
Query MySQL, MariaDB or Aurora MySQL, run statements, and load pipeline rows into tables, creating the table or new columns when needed.
- Default port
- 3306
- Encryption
- Five SSL/TLS modes, including mTLS
- Operations
- Query · Execute · Write
- Versions
- MySQL 5.7+ · MariaDB 10.2+ · Aurora MySQL · TiDB
Connect MaestroHub pipelines to MySQL databases for flexible, high-performance data ingestion and orchestration. This guide covers connection setup, security configuration, and query functions tailored for MySQL workloads.
Overview
The MySQL connector brings relational database capabilities to your MaestroHub pipelines:
- Read and write data using standard SQL queries with full parameter support
- Secure connections with five SSL/TLS modes including mutual TLS (mTLS)
- Broad compatibility with MySQL 5.7+, MariaDB 10.2+, Aurora MySQL and TiDB
The MySQL connector is validated with MySQL 5.7+, MariaDB 10.2+, Amazon Aurora MySQL and TiDB. See TiDB for its settings and what differs.
Connection Configuration
Creating a MySQL Connection
Navigate to Connections → New Connection → MySQL and configure the following:
MySQL Connection Creation Fields
1. Profile Information
| Field | Default | Description |
|---|---|---|
| Profile Name | - | A descriptive name for this connection profile (required, max 100 characters) |
| Description | - | Optional description for this MySQL connection |
2. Database Configuration
| Field | Default | Description |
|---|---|---|
| Host | localhost | MySQL server hostname or IP address (required) |
| Port | 3306 | MySQL server port (1-65535) |
| Database | - | Database name to connect to (required) |
| Connection Timeout | 30s | Maximum time to wait for connection establishment, as a duration (1s-5m) |
Note: Compatible with MySQL 5.7+, MariaDB 10.2+, and Aurora MySQL.
3. Basic Authentication
| Field | Default | Description |
|---|---|---|
| Username | - | MySQL database user |
| Password | - | MySQL user password |
4. SSL/TLS Settings
4a. SSL Mode
| Field | Default | Description |
|---|---|---|
| SSL Mode | preferred | TLS/SSL connection mode (disabled / preferred / required / verify-ca / verify-identity) |
SSL Mode Options
disabled: No encryption, data transmitted in plain textpreferred: Use TLS if the server supports it; fall back to unencrypted otherwise (default)required: Enforce TLS encryption; fail if the server does not support itverify-ca: Enforce TLS and verify the server certificate against a trusted CA (the hostname is not checked)verify-identity: Enforce TLS, verify CA, and also verify the server hostname matches the certificate
4b. Certificate Configuration
(Only displayed when SSL Mode is verify-ca or verify-identity)
| Field | Default | Description |
|---|---|---|
| CA Certificate | - | Trusted CA certificate in PEM format. Only required for self-signed or private CA certificates; leave empty for public CAs |
| Client Certificate | - | Optional client certificate in PEM format for mutual TLS (mTLS) |
| Private Key | - | Private key corresponding to the client certificate in PEM format |
5. Connection Pool Settings
| Field | Default | Description |
|---|---|---|
| Max Open Connections | 100 | Maximum number of simultaneous database connections (1-1000). Higher values increase concurrency but add DB load |
| Max Idle Connections | 25 | Idle connections kept ready for reuse to reduce latency (0-1000, 0 = close idle connections immediately) |
| Connection Max Lifetime | 15m | Maximum age of a connection before it is recycled (a duration, 0s-24h in whole seconds, 0s = keep connections indefinitely). Helps avoid server-side timeouts |
| Connection Max Idle Time | 5m | How long an idle connection may remain unused before being closed (a duration, 0s-24h in whole seconds, 0s = disable idle timeout) |
Connection pool settings help optimize database performance by balancing concurrency, resource usage, and latency across workloads.
6. Retry Configuration
| Field | Default | Description |
|---|---|---|
| Retries | 3 | Retries after the first connection attempt fails (0-10, 0 = no retries). Each retry waits the Retry Delay first; the delay grows by the Backoff Multiplier after every retry |
| Retry Delay | 200ms | Initial delay before the first retry, as a duration such as 200ms or 2s (0s-1m) |
| Retry Backoff Multiplier | 2 | Exponential factor for retry delay growth (1.0-10.0, e.g., 2 means delay doubles each retry) |
Retry Behavior Example
- 1st retry: wait 200ms
- 2nd retry: wait 400ms (200 × 2)
- 3rd retry: wait 800ms (400 × 2)
7. Connection Labels
| Field | Default | Description |
|---|---|---|
| Labels | - | Key-value pairs to categorize and organize this MySQL connection (max 10 labels) |
Example Labels
env: prod: Environmentteam: data: Responsible teamregion: us-east: Geographical region
- Required Fields: All fields described as "required" must be filled.
- SSL/TLS: When SSL Mode is set to
disabled, no encryption is used. Usepreferredfor opportunistic encryption orrequiredand above for enforced encryption. - Certificate Fields: CA Certificate, Client Certificate, and Private Key are only shown when SSL Mode is
verify-caorverify-identity. - Connection Pooling: Manages concurrency with
Max Open Connections, reduces latency withMax Idle Connections, mitigates stale connections viaConnection Max Lifetime, and frees resources usingConnection Max Idle Time. - Retry Logic: Implements exponential backoff: initial connection attempts use the base delay and each retry multiplies the delay by the backoff factor; ideal for transient network issues or database restarts.
- Timeout Values:
Connection Timeoutapplies to initial connection establishment; every time value is a duration that carries its unit, such as30s,500msor15m. - Security Best Practices: Always use
requiredor stricter SSL modes for production. Preferverify-identityand supply CA certificates for maximum security. Use client certificates for mutual TLS when possible.
Function Builder
Creating MySQL Functions
Once you have a connection established, you can create reusable functions for different operation types:
- Open the connection and go to its Functions tab → New Function
- Select one of the MySQL function types: Query, Execute, or Write
- Configure the function parameters
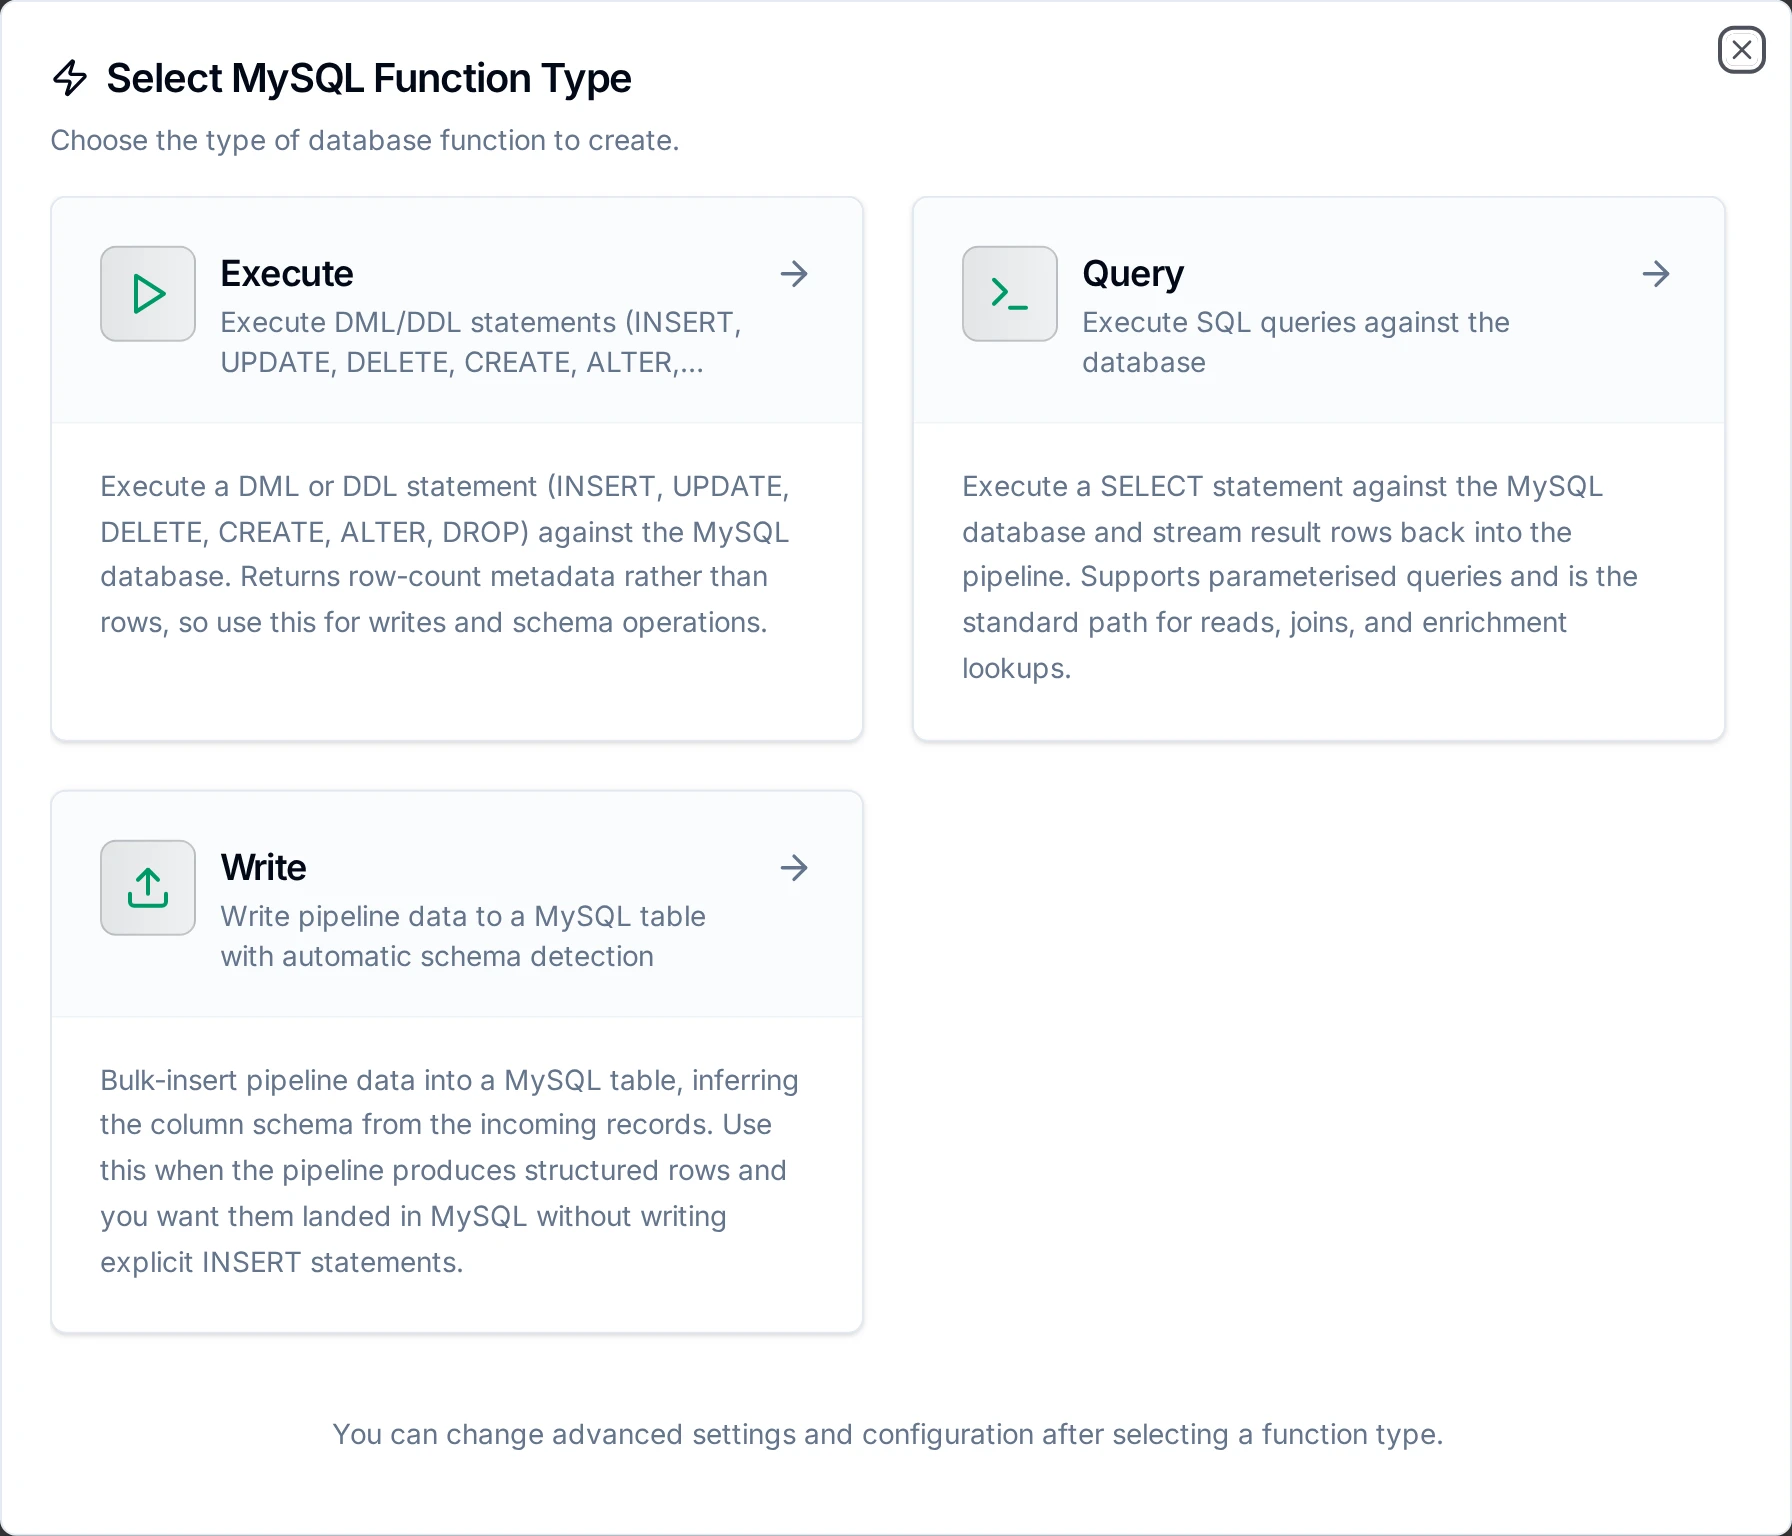
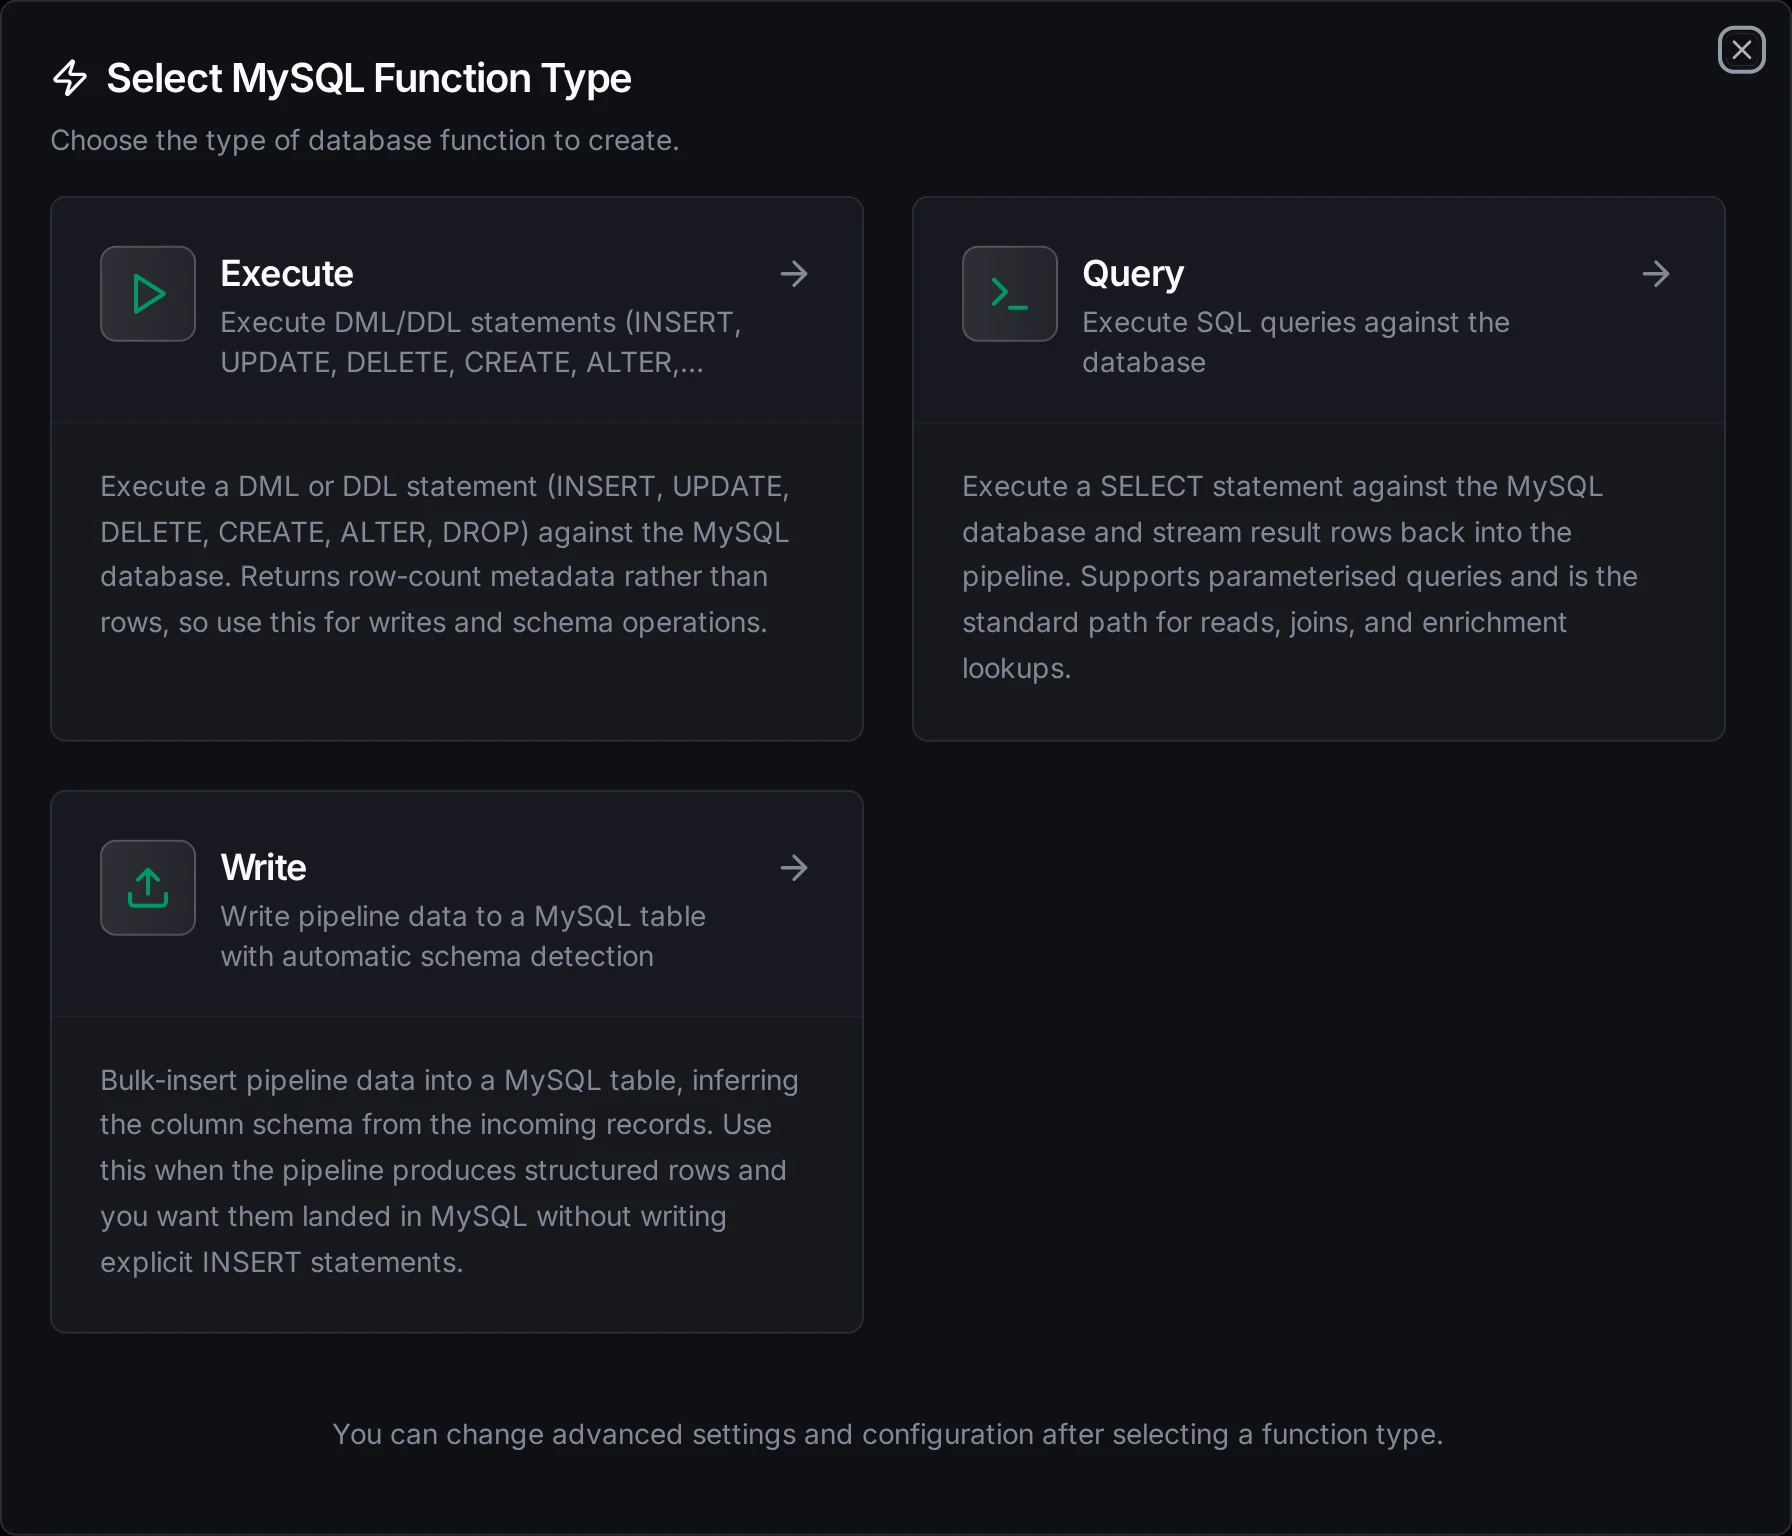
MySQL function creation interface showing available function types: Query, Execute, and Write
Query Function
Purpose: Execute SQL queries (SELECT) to read data from MySQL. Returns rows as structured data.
Configuration Fields
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| SQL Query | String | Yes | - | SQL SELECT statement to execute. Supports parameterized queries with ((param)) syntax. |
| Timeout | Duration | No | 30m | Per-execution timeout (1s-1h). |
Use Cases:
- SELECT machine KPIs (OEE, downtime) from telemetry tables
- SELECT COUNT(*) from orders grouped by status
- SELECT with JOINs across multiple tables
- SELECT with WHERE filters and ORDER BY
Execute Function
Purpose: Execute DML/DDL statements (INSERT, UPDATE, DELETE, CREATE, ALTER, DROP) on MySQL. Returns rowsAffected instead of row data. Use this for data modifications and schema changes.
Configuration Fields
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| SQL Statement | String | Yes | - | DML/DDL SQL statement to execute. Supports parameterized queries with ((param)) syntax. |
| Timeout | Duration | No | 30m | Per-execution timeout (1s-1h). |
Use Cases:
- INSERT production events (start/stop, shift logs, quality checks)
- UPDATE work orders, inventory counts, or maintenance schedules
- DELETE or archive old telemetry and audit logs
- CREATE TABLE or ALTER TABLE for schema changes
Write Function
Purpose: Write pipeline data to a MySQL table with automatic schema detection. This is not a SQL editor: it loads structured data (rows/objects) from your pipeline into a target table.
Write reads the table's columns and maps the incoming data fields to them automatically. Supports batching for efficient bulk loading.
Configuration Fields
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| Table Name | String | Yes | - | Target table to insert data into. |
| Data | JSON | Yes | - | Rows to write: an array of objects or a single object. Use ((data)) to take them from the pipeline, or enter static JSON. |
| Create Table If Not Exists | Boolean | No | false | Create the table if it does not exist, with column types from the Schema or inferred from the data. |
| Allow Schema Evolution | Boolean | No | false | Add a column to an existing table when the data carries a field the table has no column for. When off, such a batch fails instead of dropping the field. See step 5 below. |
| Schema | JSON | No | - | Column definitions (types, primary keys, indexes) for creating the table, set in the Visual Editor or as JSON. Shown when Create Table If Not Exists is on. Rendered from a template, the schema is data: a default value, a check expression or anything but a plain type is refused. |
| Batch Size | Number | No | 100 | Number of rows per INSERT batch (1-10,000). |
| Timeout | Duration | No | 30m | Per-execution timeout (1s-1h). |
Use Cases:
- Auto-detect table schema and map pipeline data
- Create tables on-the-fly from pipeline data
- Bulk insert production events with auto schema detection
How Write Works Step by Step
1. Batching
Each batch generates a single INSERT INTO `table` (`col1`, `col2`) VALUES (?, ?), (?, ?) statement with multiple value tuples. If your pipeline sends 10 rows and Batch Size is 5, exactly 2 INSERT statements are executed (2 batches of 5 rows). If it sends 13 rows, 3 INSERT statements are executed (5 + 5 + 3).
2. Column Matching
Write uses case-insensitive matching between incoming data field names and table column names. For example, a data field named deviceId will match a table column DEVICEID or deviceid. The original column casing from the database is preserved in the generated INSERT statement.
3. Table Exists: Normal Flow
- The function first queries
INFORMATION_SCHEMAto check if the target table exists - If the table exists, it fetches all column metadata (name, type, nullability)
- If the data carries fields that have no column in the table, Allow Schema Evolution decides: when on, the missing columns are added first (step 5); when off, the write fails and nothing is inserted
- It matches incoming data fields to table columns (case-insensitive)
- Batch INSERT statements are generated and executed using the matched columns
4. Table Does Not Exist
| Create Table If Not Exists | Behavior |
|---|---|
| Disabled (default) | Returns an error immediately: "table 'X' does not exist. Enable 'Create table if not exists' or create it manually". No insert is attempted. |
| Enabled, no schema provided | Types are inferred from all rows in the batch using the rules below. A CREATE TABLE is executed, then all rows are inserted. |
| Enabled, with schema | The provided schema is used for CREATE TABLE with full column definitions (types, primary keys, indexes). After creation, all rows are inserted. |
Data Type Inference: when no schema is provided, the Write function infers each column's type from all rows in the batch. For each field it uses the first row where the field has a non-null value; a field that is null in every row gets the null type below. A row that lacks a field inserts NULL for it.
| Data Value | Inferred Type | Notes |
|---|---|---|
true / false | TINYINT(1) | JSON boolean values |
42, -7, 1000 | BIGINT | Whole numbers (no fractional part) |
3.14, 0.5 | DOUBLE | Numbers with fractional part |
"2024-01-15T10:30:00Z" | DATETIME | Strings matching ISO 8601 / RFC 3339 and other common timestamp formats are automatically detected |
"hello", "sensor-01" | TEXT | All other strings |
null | TEXT | Null values default to text |
{"key": "val"}, [1,2] | TEXT | Objects and arrays are stored as JSON text |
JSON has a single number type, so 55.0 arrives as 55 and is typed BIGINT. When rows disagree, a whole number gives way to a later number with a fractional part: a field that is 38 in one row and 38.5 in a later row gets DOUBLE. Any other disagreement keeps the type of the first non-null value, so a field that is a string in the first row stays TEXT even if later rows send numbers. If you need a specific numeric type (e.g., DECIMAL, INT), define it in the schema using the Visual Editor.
5. Schema Evolution (Table Exists + Allow Schema Evolution On)
When Allow Schema Evolution is on and the table already exists, the function adds the missing columns before inserting:
- New columns: If the data contains fields that have no column in the table,
ALTER TABLE ADD COLUMNis executed for each missing field. If a schema is defined in the Visual Editor, the specified type is used; otherwise, the type is inferred from the batch using the rules above. - After the columns are added, column metadata is re-fetched from the database, then all rows are inserted with the updated column set.
Schema evolution only adds columns; it never changes the type of an existing column. Data that does not fit an existing column's type is not handled by schema evolution: the database rejects or converts it as it would for any INSERT.
The following changes are not made by schema evolution and require manual ALTER TABLE statements:
- Changing the type of an existing column, whether widening or narrowing it
- Changing an already-created column's type by updating the Visual Editor schema alone, because the schema definition only affects new columns being added
- Dropping columns: removing a column from the Visual Editor schema does not delete it from the database table. The column remains in the table and receives
NULL(or its default value) for new inserts.
If you need to change an existing column's type or drop a column, use the Execute function to run ALTER TABLE ... MODIFY COLUMN ... or ALTER TABLE ... DROP COLUMN ... manually.
Allow Schema Evolution off: if the data carries a field that has no column in the table, the write fails before anything is inserted, with an error that names the fields:
write batch carries field(s) [pressure] with no matching column in table "sensor_readings" and schema evolution is disabled — enable 'Allow schema evolution' on this function, or add the column(s) manually
Turn the switch on, add the column with the Execute function, or remove the field upstream. The error is marked permanent because the same batch would fail again: with Store & Forward on, the batch is not retried and goes to Failed messages.
Functions saved before the switch existed have no Allow Schema Evolution value. For them, Create Table If Not Exists decides: when on, missing columns are added; when off, fields that have no column are skipped and listed in skippedFields. When you open such a function in the editor, the switch starts in the same position as Create Table If Not Exists, and saving stores it. Once it is saved as off, a batch with an unknown field fails instead of being skipped.
6. Partial Failure
Each batch executes independently: there is no transaction wrapping all batches. If batch 3 of 5 fails, batches 1 and 2 have already been committed. The error response still includes rowsInserted showing how many rows succeeded before the failure.
Response Metadata
On success, the response includes:
| Field | Description |
|---|---|
rowsInserted | Total number of rows successfully inserted |
matchedColumns | Column names that had matching data fields (when the table already existed) |
skippedFields | Data fields that had no matching column and were skipped; only for functions saved before Allow Schema Evolution existed (if any) |
schemaEvolution | Columns added by schema evolution, each with its type (if any) |
tableCreated | true if the table was created during this call |
columns | Columns written to (when the table was created during this call) |
batchSize | Batch size used |
totalRows | Total number of input rows |
Using Parameters
MaestroHub detects the ((parameterName)) syntax and exposes each parameter for validation and runtime binding for Query and Execute functions.
| Configuration | Description | Example |
|---|---|---|
| Type | Enforce data types for incoming values | string, number, boolean, date, array |
| Required | Mark parameters as mandatory or optional | Required / Optional |
| Default Value | Fallback value applied when callers omit a parameter | NOW(), 0, 'active' |
| Description | Add guidance for downstream users | "Start date for the report" |
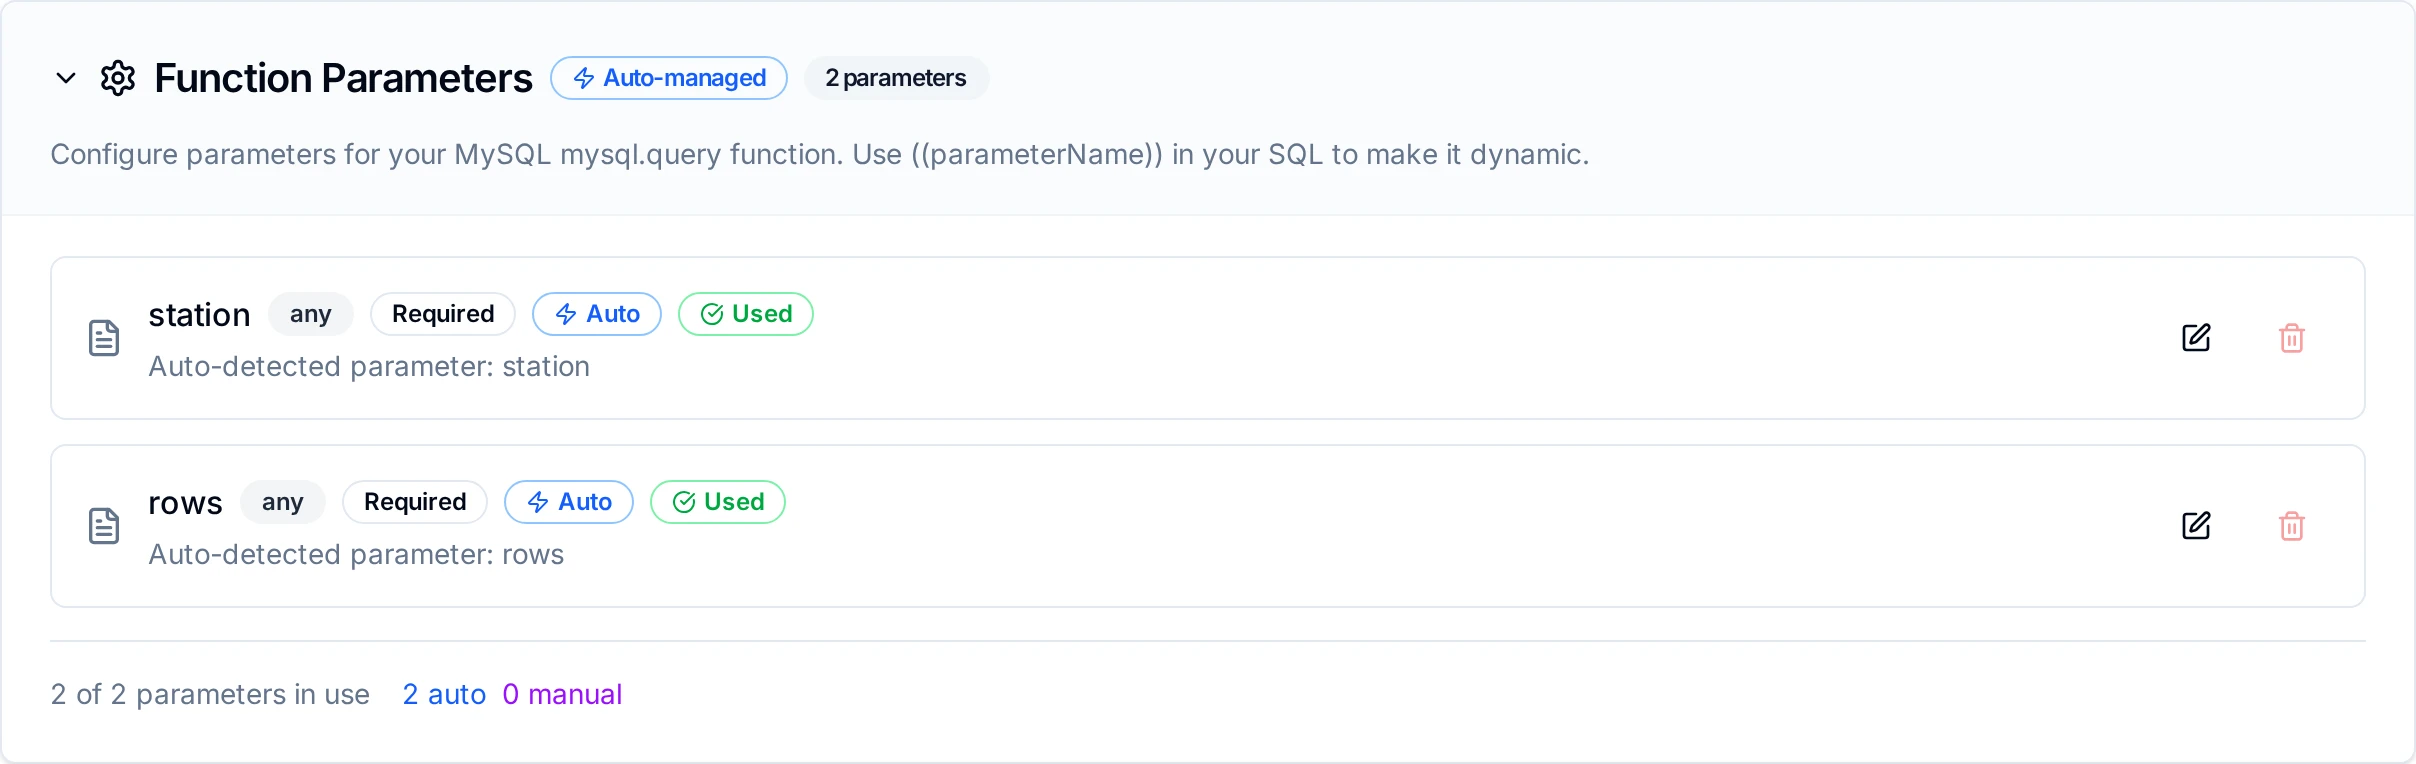
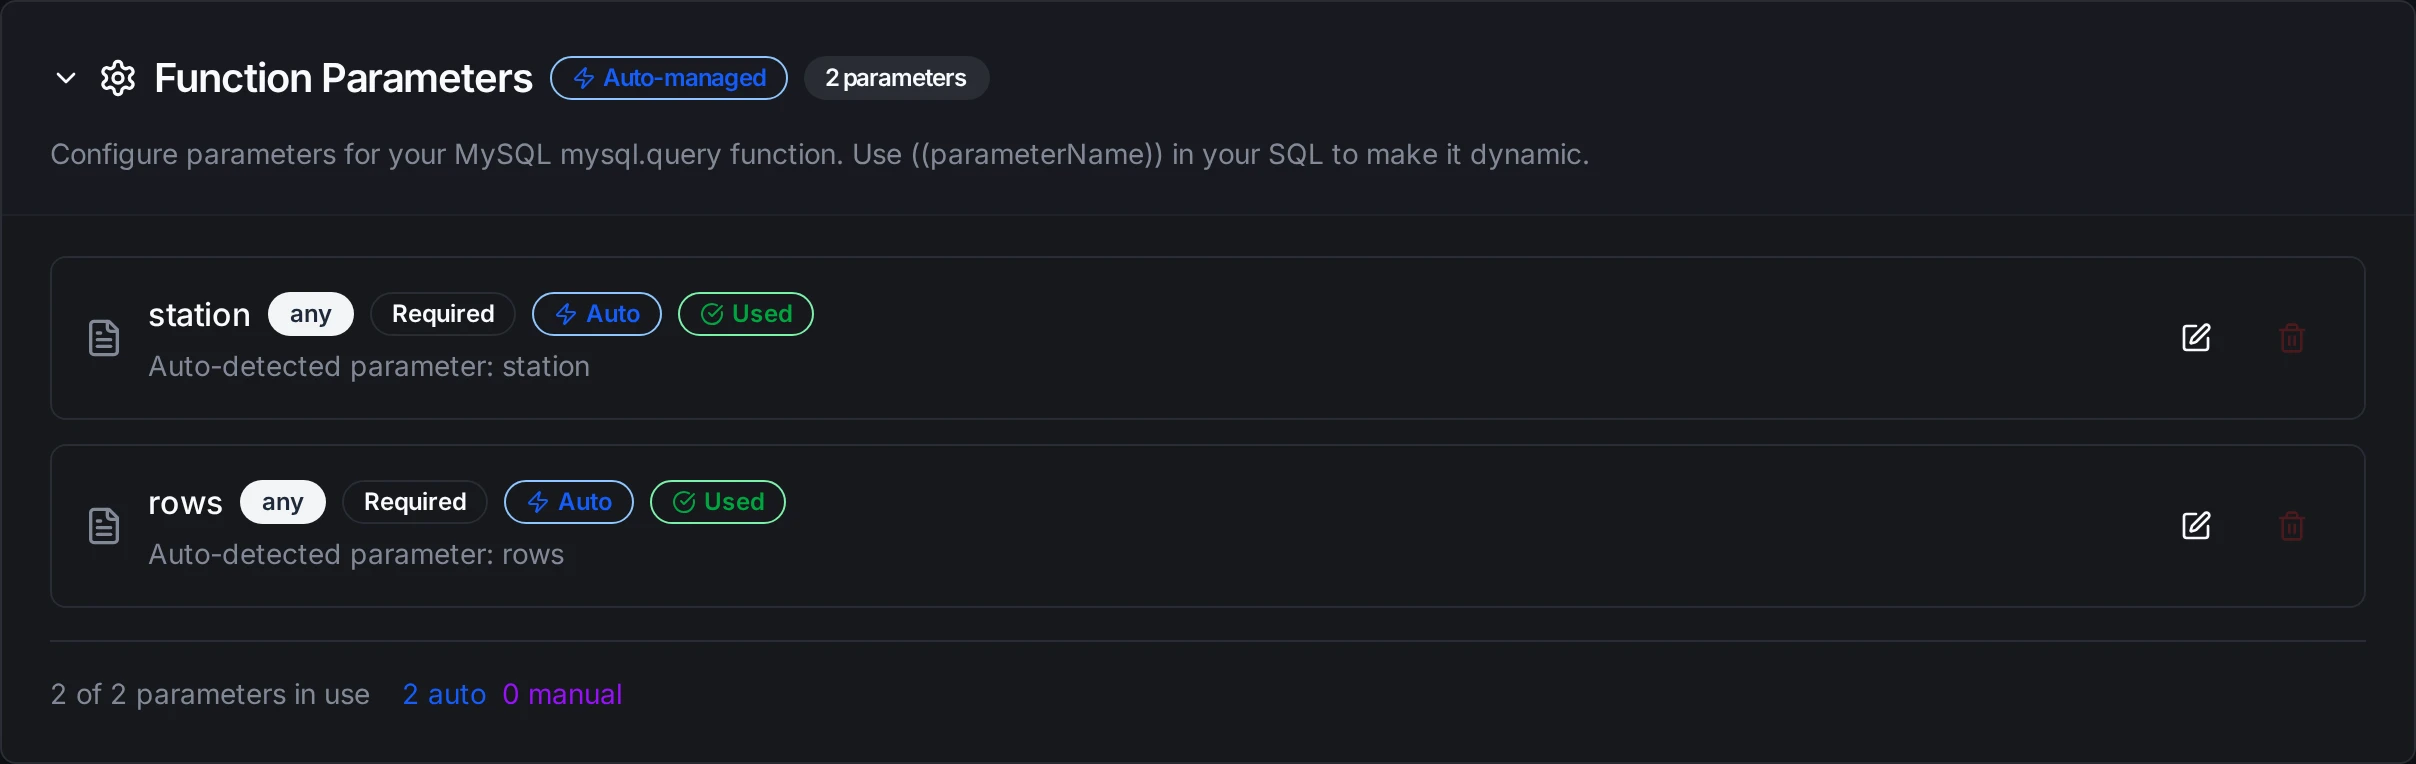
Parameter configuration with validation rules and helper text
TiDB
TiDB is a distributed SQL database that speaks the MySQL wire protocol, so the MySQL connector reaches it as it is: there is no separate TiDB connector to choose. Search the new-connection picker for tidb or pingcap and it offers MySQL.
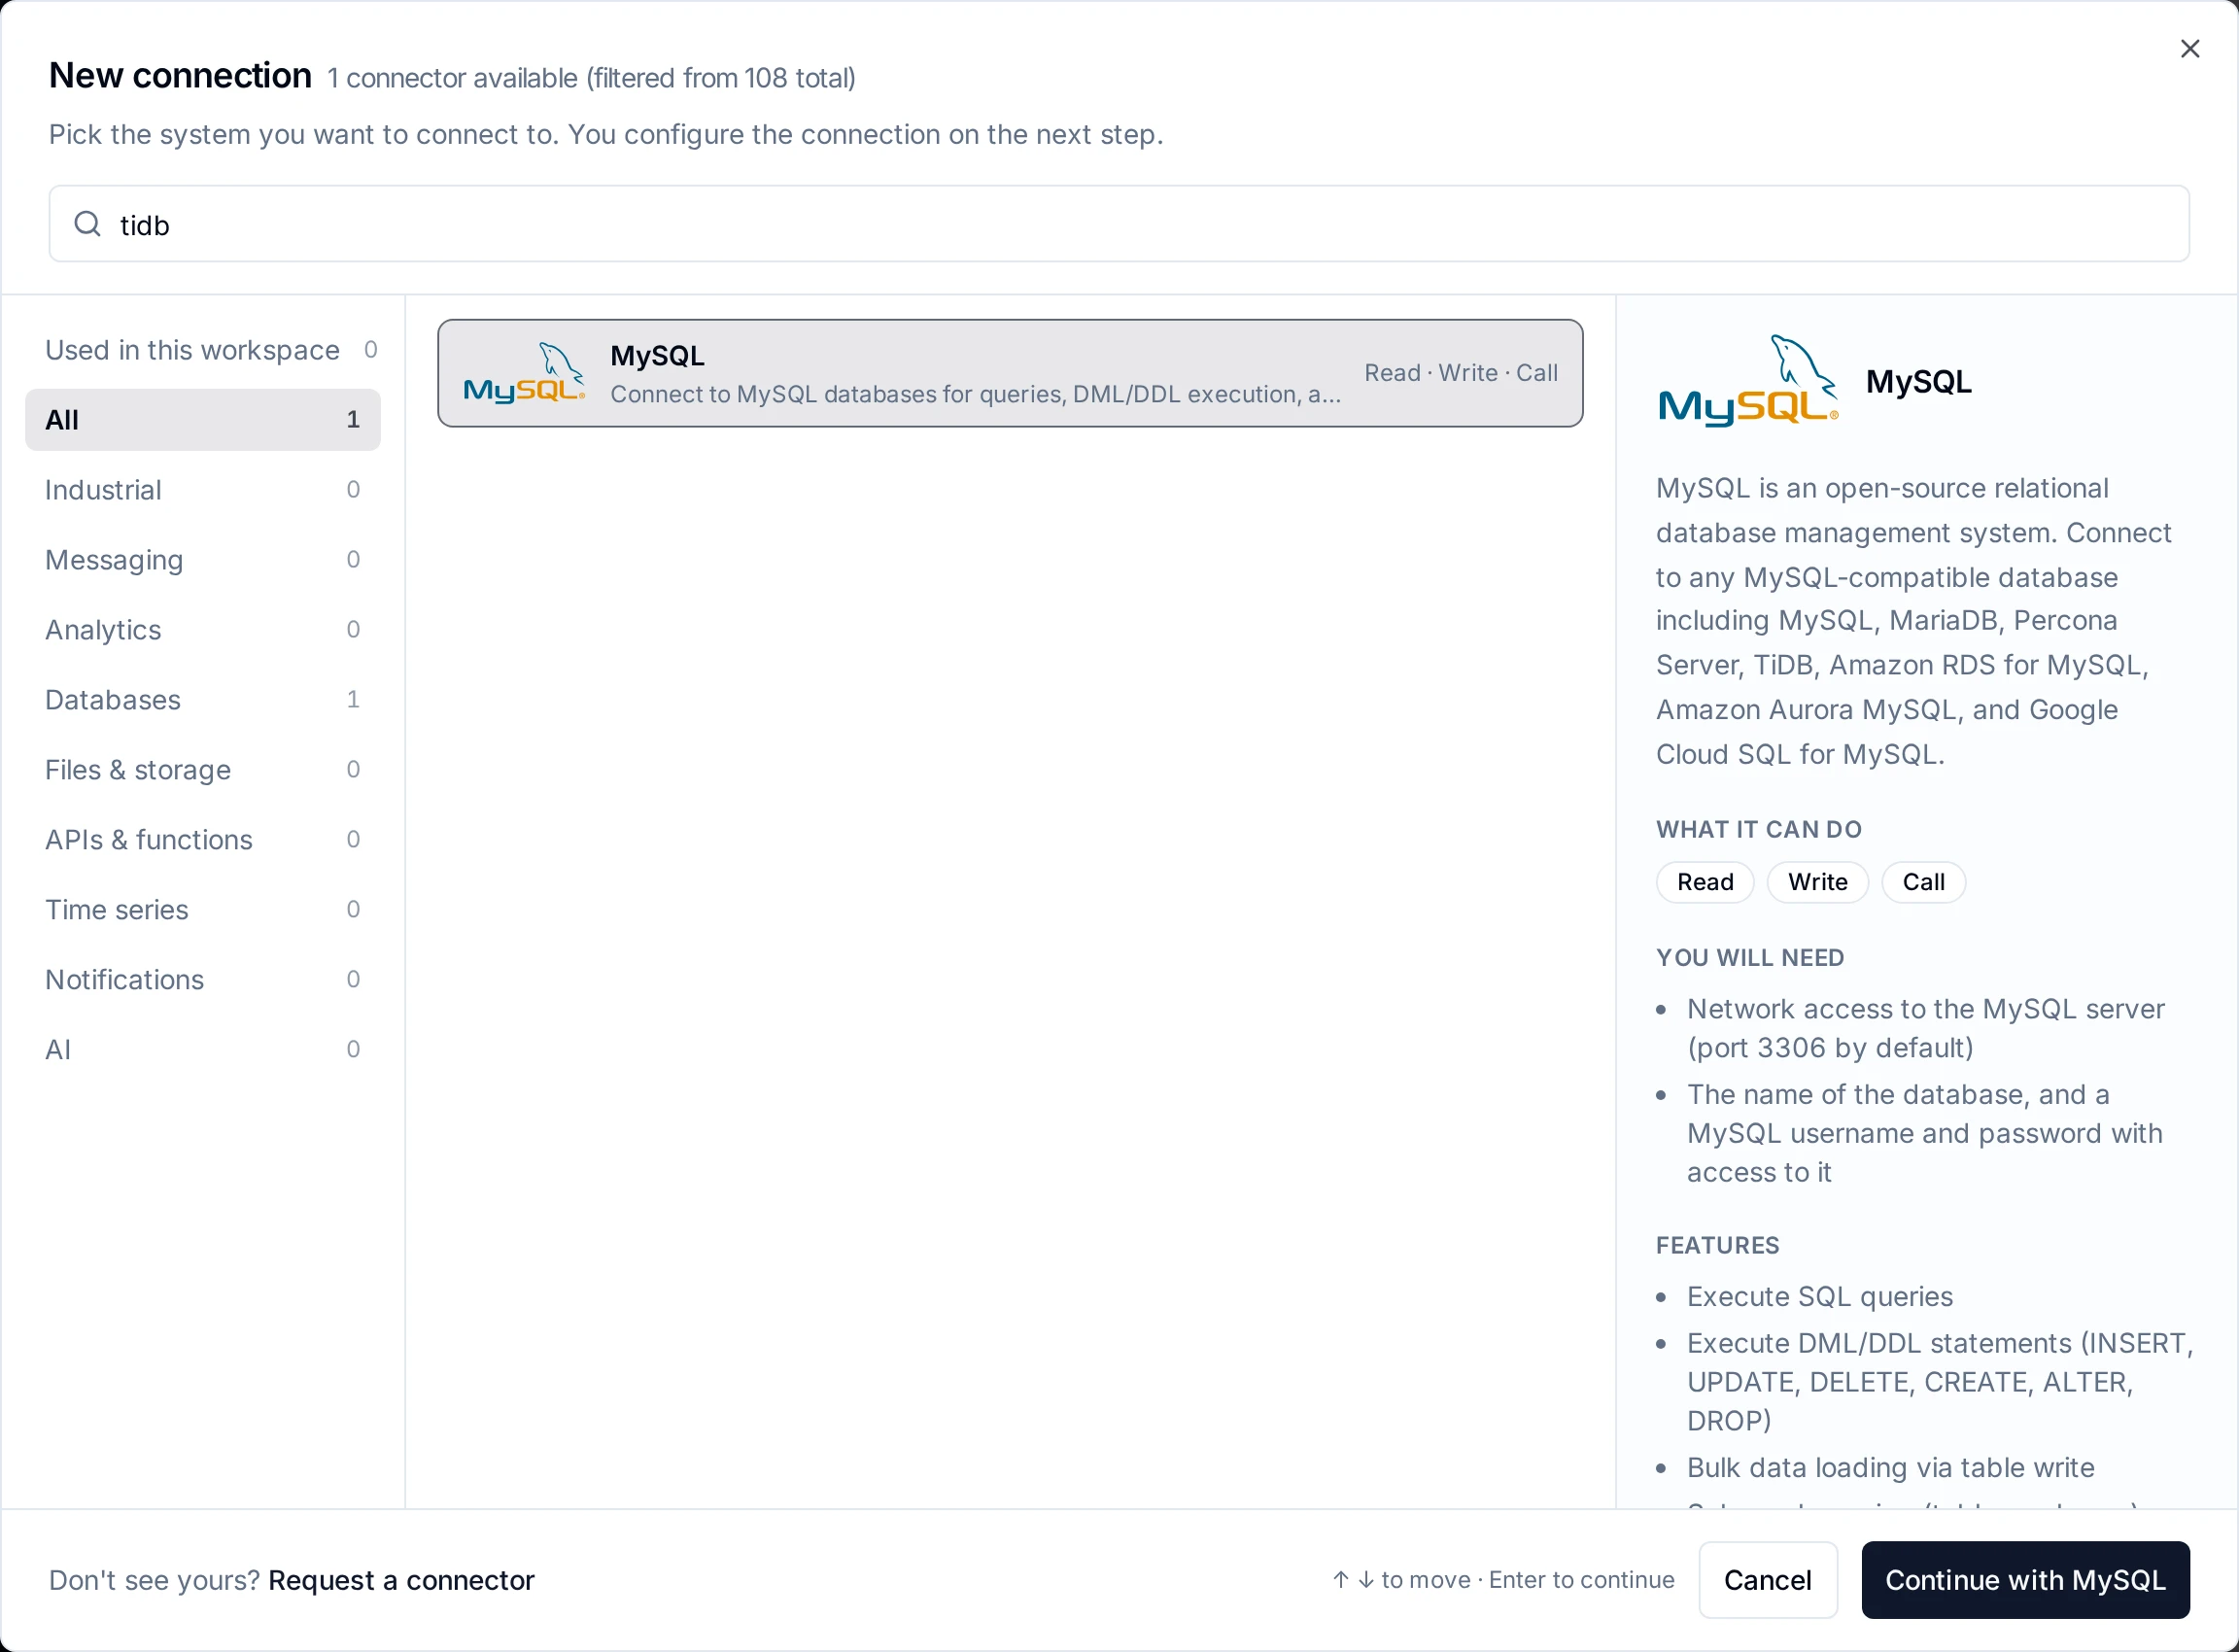
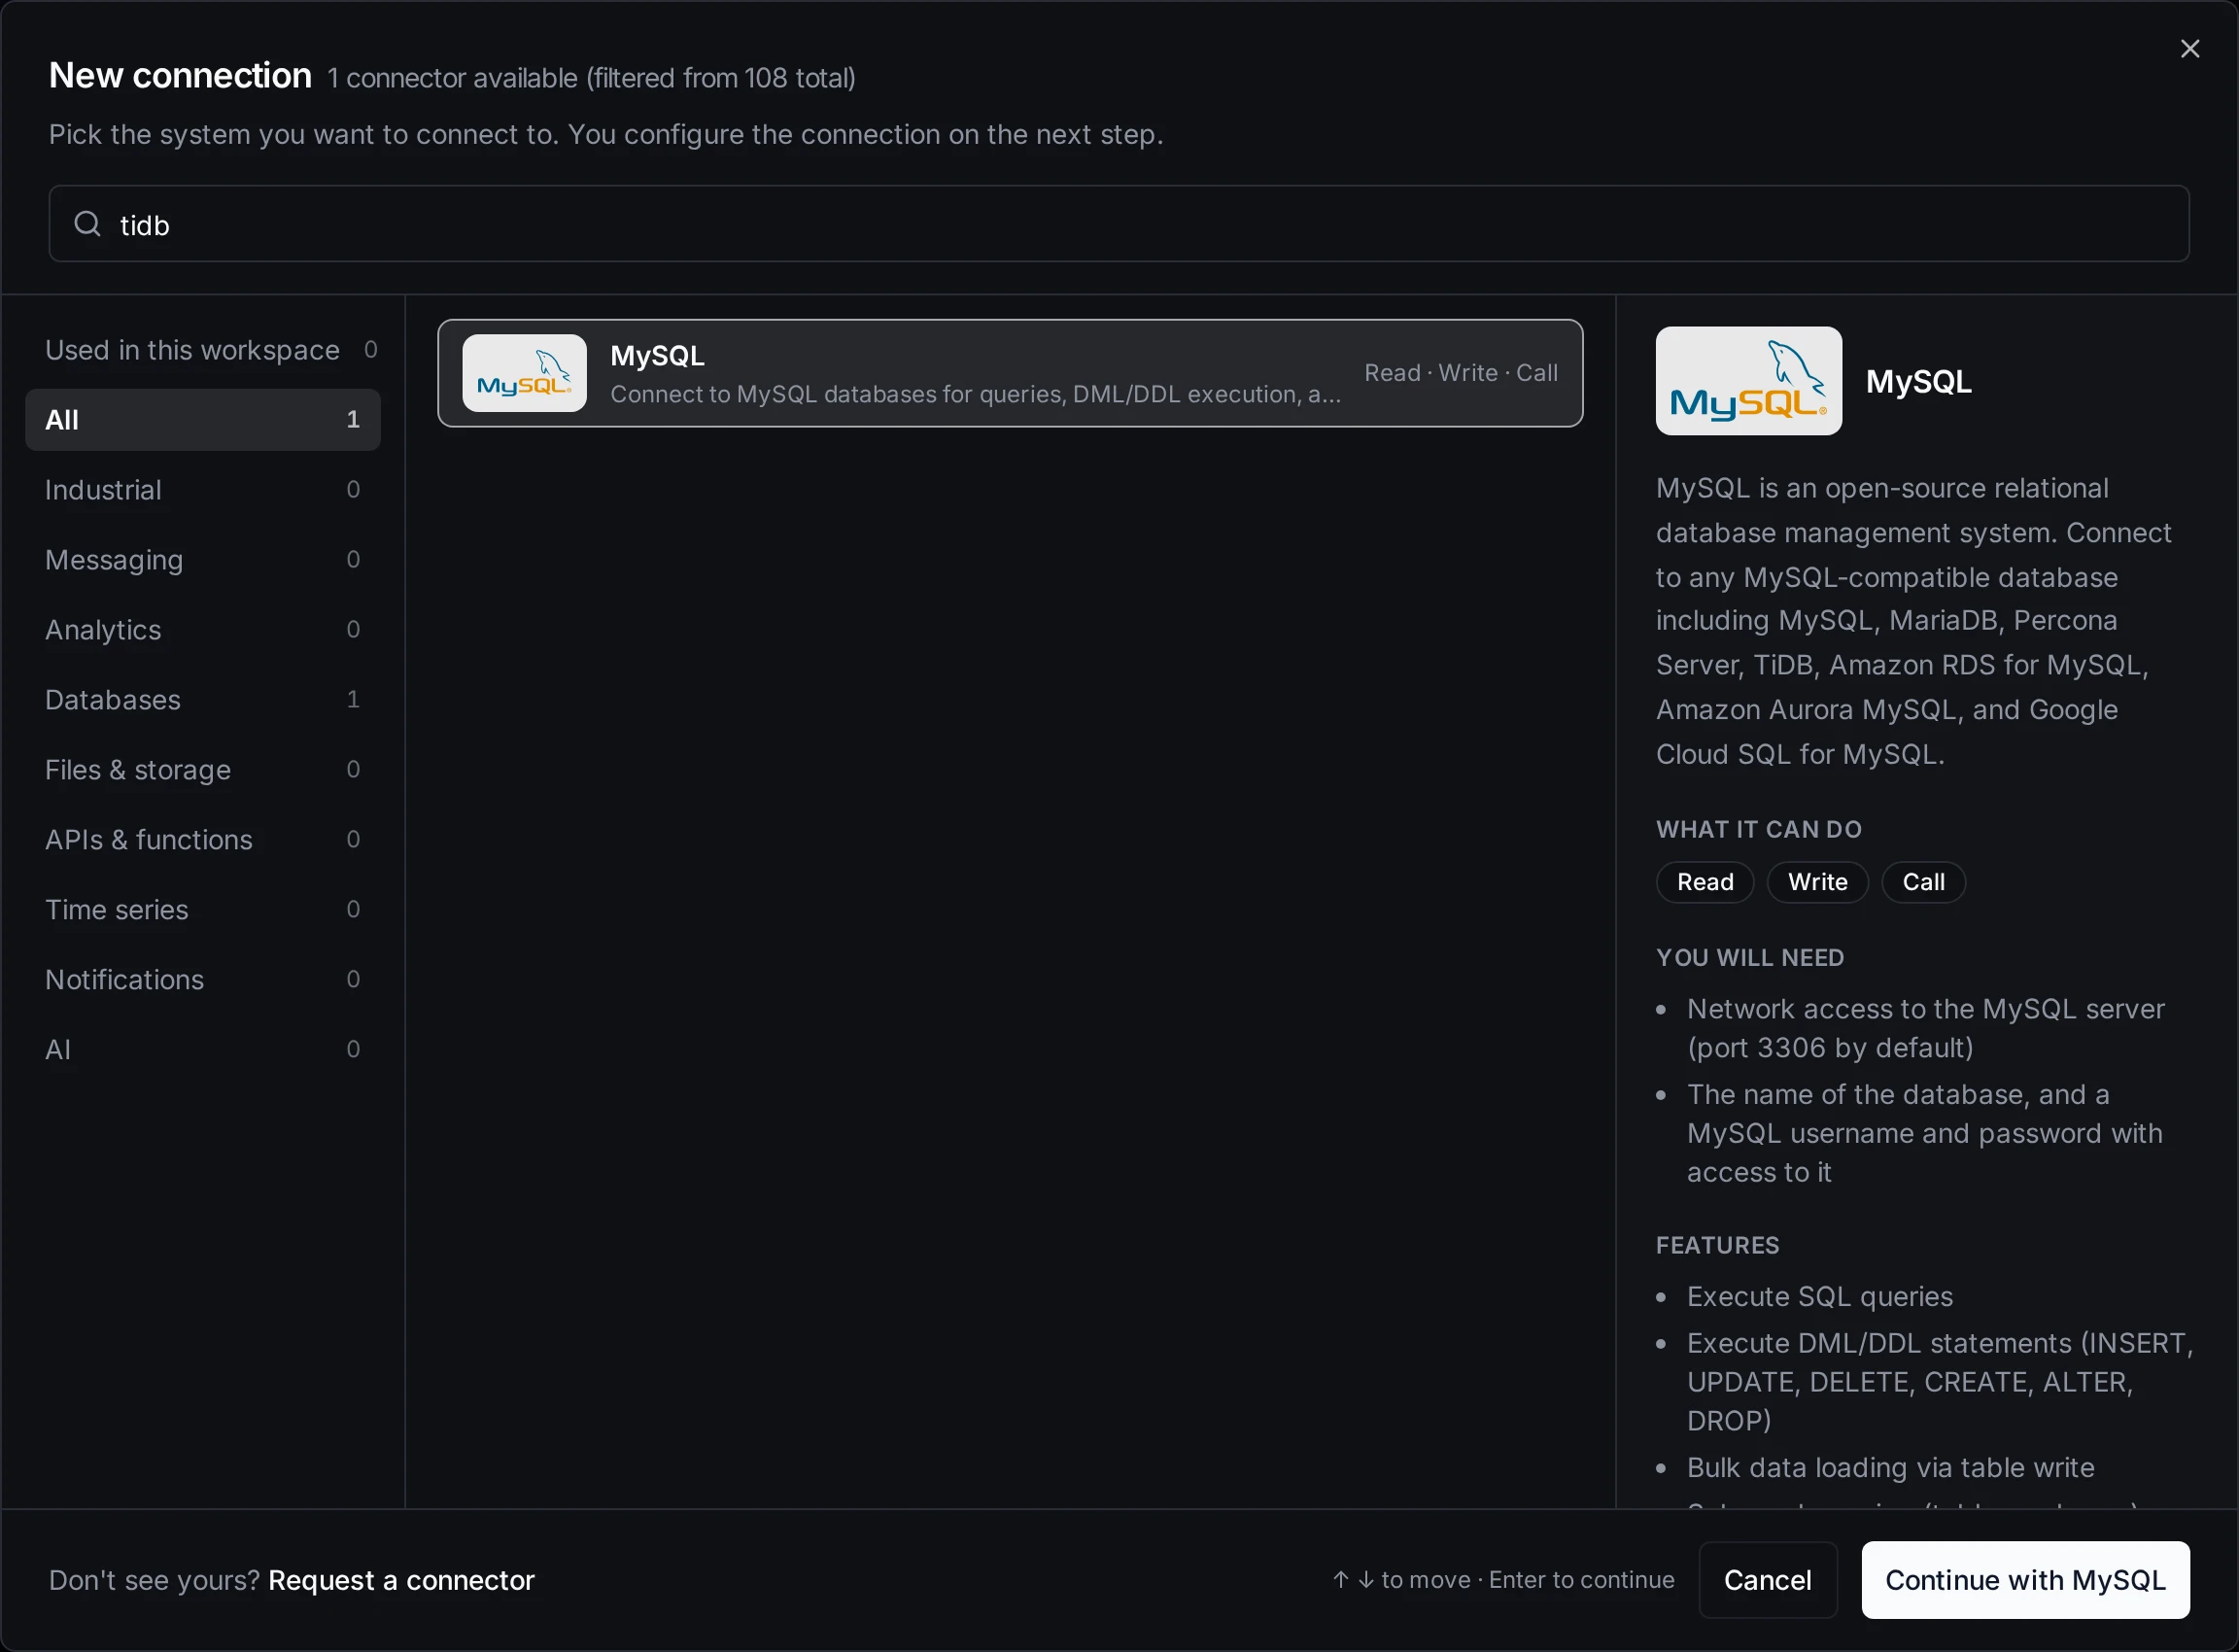
Searching the picker for tidb finds the MySQL connector
Query, Execute and Write, the Query tab and its schema browser, and the SSL modes disabled, required, verify-ca and verify-identity with client certificates work against TiDB as against MySQL. They were checked against TiDB 8.5 with the connector's whole MySQL test suite, the shared write conformance suite included.
Connecting
| Field | TiDB value |
|---|---|
| Host | A TiDB server, or the load balancer in front of the TiDB servers |
| Port | 4000 (TiDB's default; not MySQL's 3306) |
| Database | The database, such as mes |
| Username / Password | A user created with CREATE USER 'maestro'@'%' IDENTIFIED BY '…' and granted the database |
| SSL Mode | verify-identity with the server's CA certificate when TLS is set up ([security] ssl-ca, ssl-cert, ssl-key in the TiDB configuration); disabled when it is not |
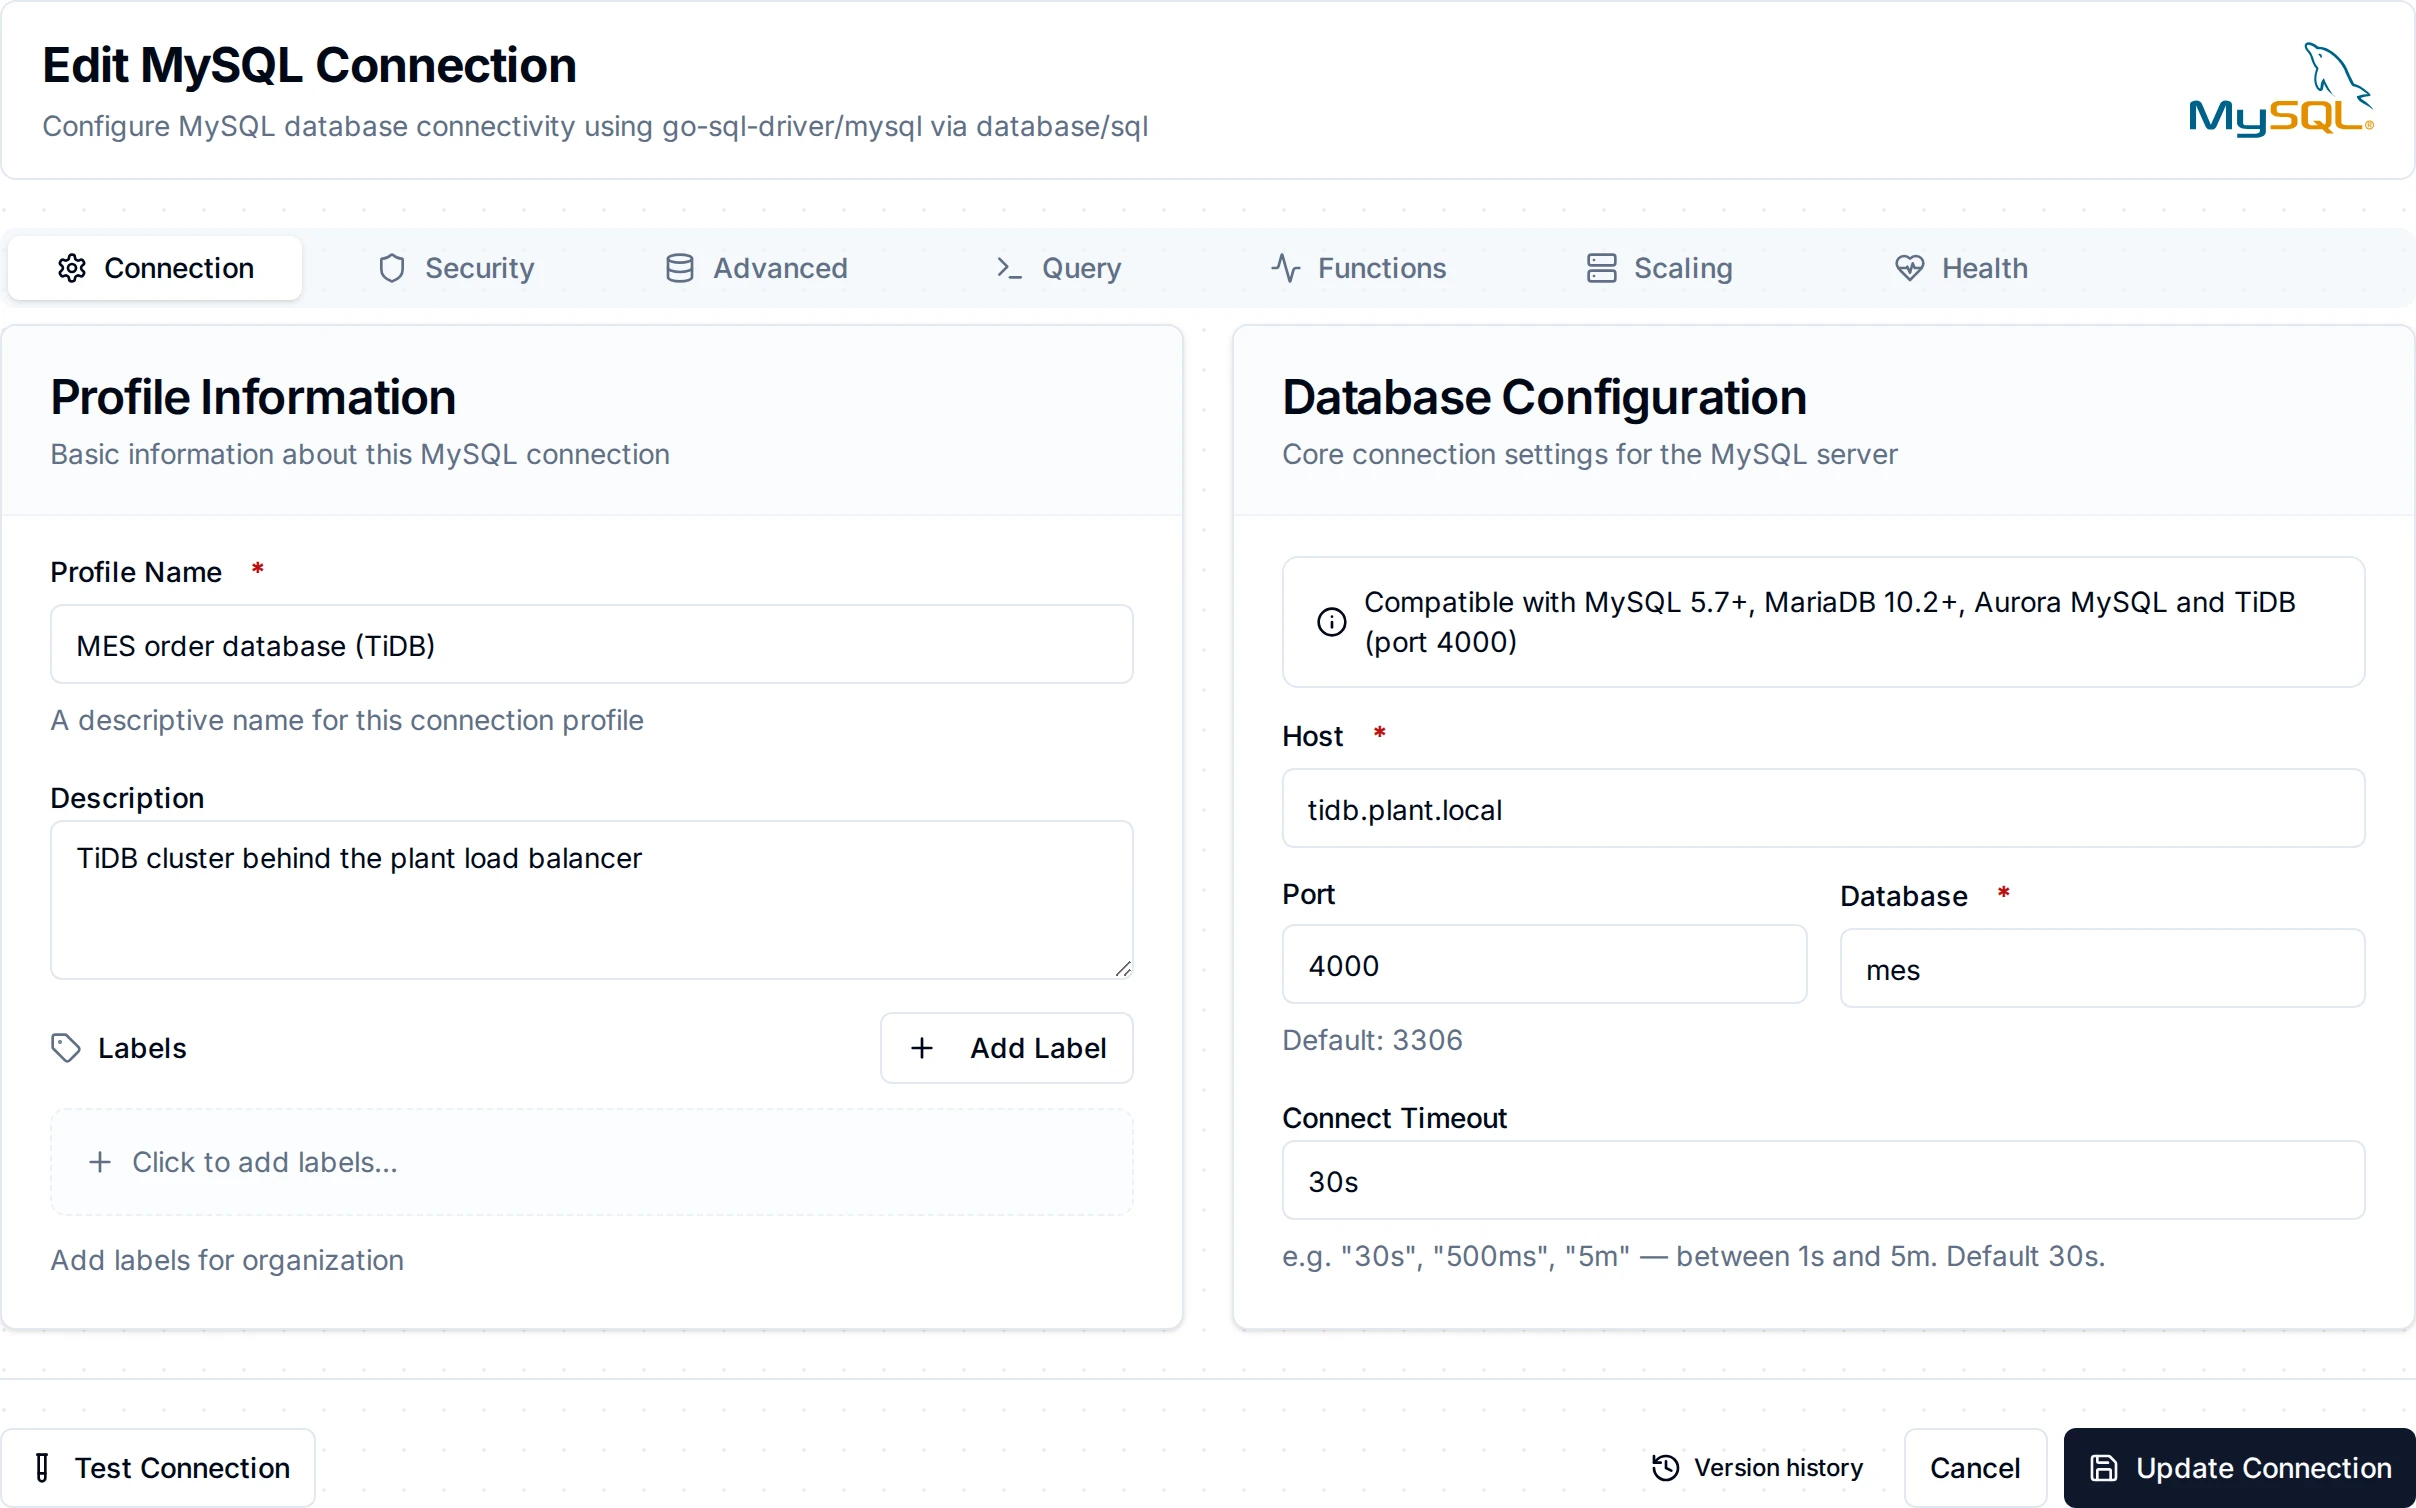
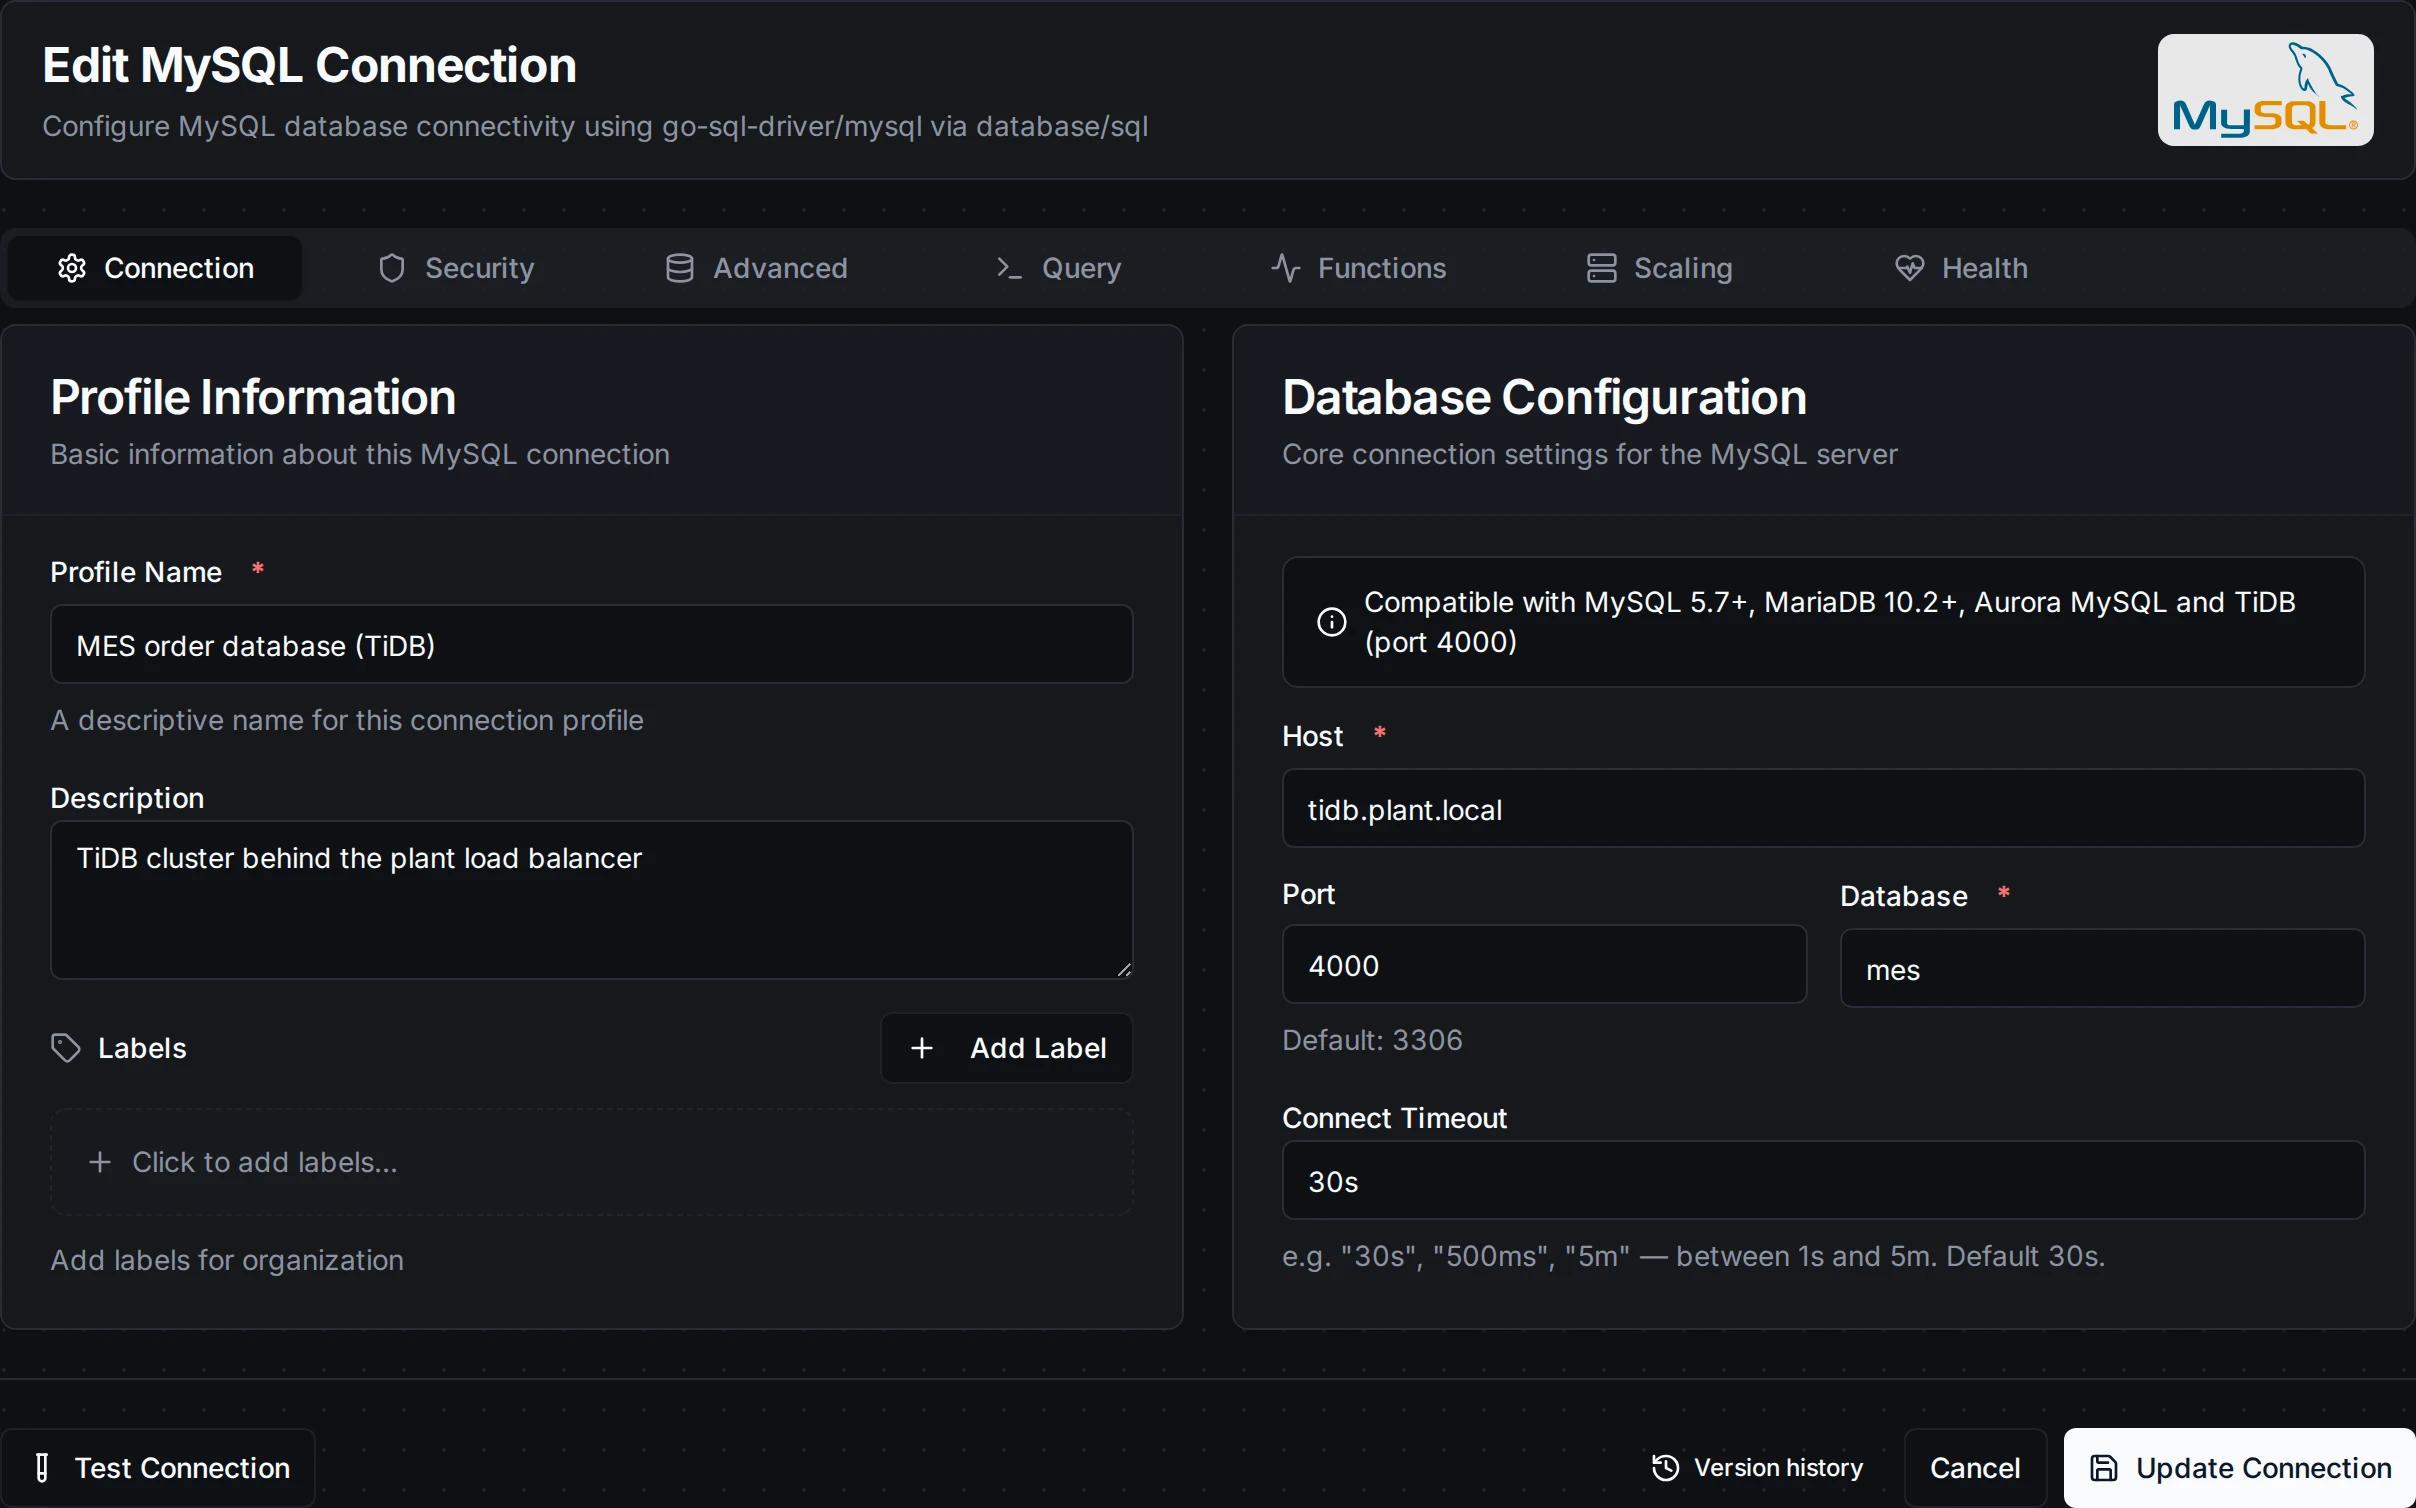
A MySQL connection filled in for a TiDB server
TiDB Cloud clusters require TLS: use verify-identity and the host name the Cloud console gives. This was not tried against a Cloud cluster.
What differs from MySQL
| TiDB | What MaestroHub does | |
|---|---|---|
| Write conflicts | In optimistic mode a transaction that lost a race fails at COMMIT with error 9007 Write conflict; 8022, 8028 (information schema is changed) and 9005 also ask for a retry. | All are transient: the platform retries the write, never dead-letters it. |
| Adding columns | ALTER TABLE … ADD COLUMN runs online, in steps. The column shows in INFORMATION_SCHEMA.COLUMNS some milliseconds before a statement may use it. | Write matches fields only to columns it can use, so writes that add the same new column at once all land, instead of one failing with Unknown column. |
| CHECK constraints | Parsed, but enforced only when tidb_enable_check_constraint is on, which it is not by default. | A row the constraint would refuse is written. Turn the setting on (SET GLOBAL tidb_enable_check_constraint = ON) if you rely on CHECK constraints. |
| AUTO_INCREMENT | Unique, but not consecutive: each TiDB server hands out ids from its own block. | Nothing to do; do not rely on ids being consecutive. |
| Upserts | INSERT … ON DUPLICATE KEY UPDATE works. | Use it in an Execute function. |
| Query timeout | MAX_EXECUTION_TIME is supported. | The function's Request Timeout ends a long query, as on MySQL. |
Pipeline Integration
Use the MySQL functions you create here as nodes inside the Pipeline Designer to integrate your MySQL databases with the rest of your operations stack. Drag the appropriate node type onto the canvas, bind its parameters to upstream outputs or constants, and configure connection-level options without leaving the designer.
Each function type maps to a dedicated pipeline node (Query, Execute, and Write), so you can clearly separate read, write, and data-loading operations in your flows.
For end-to-end orchestration ideas, such as combining database reads with MQTT, REST, or analytics steps, explore the Nodes page to see how SQL nodes complement other automation patterns.
Common Use Cases
Query: Reading Production Metrics
Scenario: Generate hourly production reports with efficiency metrics from MySQL tables.
SELECT
    DATE_FORMAT(event_time, '%Y-%m-%d %H:00:00') AS hour_bucket,
    line_id,
    COUNT(*) AS event_count,
    ROUND(AVG(efficiency), 2) AS avg_efficiency,
    MIN(efficiency) AS min_efficiency,
    MAX(efficiency) AS max_efficiency
FROM production_events
WHERE event_time >= ((startDate)) AND event_time < ((endDate))
GROUP BY hour_bucket, line_id
ORDER BY hour_bucket DESC;
Pipeline Integration: Feed data to visualization dashboards, BI tools, or reporting nodes.
Execute: Updating Work Order Status
Scenario: Track manufacturing progress by updating work order status in real-time.
UPDATE work_orders
SET
    status = ((newStatus)),
    completed_units = ((completedUnits)),
    completion_percentage = ROUND(((completedUnits)) / total_units * 100, 2),
    updated_at = NOW(),
    updated_by = ((userId))
WHERE order_id = ((orderId));
Pipeline Integration: Trigger this function based on production events, barcode scans, or manual workflows.
Execute: Data Retention and Cleanup
Scenario: Maintain database performance by archiving or deleting old data.
INSERT INTO sensor_readings_archive
SELECT * FROM sensor_readings
WHERE recorded_at < DATE_SUB(NOW(), INTERVAL ((retentionDays)) DAY)
LIMIT 10000;

DELETE FROM sensor_readings
WHERE recorded_at < DATE_SUB(NOW(), INTERVAL ((retentionDays)) DAY)
LIMIT 10000;
Pipeline Integration: Schedule this function to run daily or weekly via pipeline triggers (cron jobs).
Write: Bulk Loading Sensor Data
Scenario: Load real-time sensor readings from IoT devices into a MySQL table.
Configure a Write function with:
- Table Name:
sensor_readings - Create Table If Not Exists: enabled
- Allow Schema Evolution: enabled, so a new field from the devices becomes a new column instead of failing the batch
Connect it after data collection nodes (MQTT, OPC UA, Modbus, etc.) in your pipeline. The Write function automatically maps incoming fields (sensor_id, temperature, pressure, vibration) to table columns and inserts them in batches. If the table doesn't exist, it is created automatically with inferred types.