 Kafka Integration Guide
Produce messages to Kafka topics and start pipelines from messages consumed through a consumer group.
- Default port
- 9092 (PLAINTEXT)
- Authentication
- SASL PLAIN · SCRAM-SHA-256 · SCRAM-SHA-512
- Operations
- Produce · Consume
- Triggers
- Consume, as messages arrive
Connect to Apache Kafka to produce and consume messages in your pipelines. This guide covers connection setup, function configuration, and pipeline integration for Kafka deployments.
Overview
The Kafka connector enables integration with Apache Kafka distributed streaming platforms, commonly used for event streaming, log aggregation, real-time analytics, and microservice communication. It provides:
- Message production with topic targeting, key-based partitioning, custom headers, and explicit partition selection
- Message consumption with consumer group support for load balancing and fault tolerance
- SASL authentication supporting PLAIN, SCRAM-SHA-256, and SCRAM-SHA-512 mechanisms
- TLS encryption with optional certificate verification for secure broker communication
- Consumer group management with configurable session timeouts, heartbeat intervals, and auto-commit control
- Idempotent producer by default: retries never write a record twice, order within a partition holds, and an acknowledged record survives a leader failover (see Delivery guarantees)
- Template parameters for dynamic topics, keys, payloads, and headers based on runtime input
Connection Configuration
Creating a Kafka Connection
Navigate to Connections → New Connection → Kafka and configure the following:
Kafka Connection Creation Fields
1. Profile Information
| Field | Default | Description |
|---|---|---|
| Profile Name | - | A descriptive name for this connection profile (required, max 100 characters) |
| Description | - | Optional description for this Kafka connection |
2. Broker Settings
| Field | Default | Description |
|---|---|---|
| Brokers | - | Comma-separated list of bootstrap broker addresses in host:port format (e.g., broker1:9092,broker2:9092); required |
| Client ID | - | Unique identifier for this client instance (e.g., maestrohub-producer) |
| Consumer Group ID | - | Default consumer group ID for consume functions (e.g., maestrohub-consumers) |
- 9092: Default PLAINTEXT port
- 9093: Default SSL/TLS port
- 9094: Default SASL_PLAINTEXT port
Ensure you use the correct port for your broker's listener configuration.
3. SASL Authentication
| Field | Default | Description |
|---|---|---|
| Enable SASL | false | Enable SASL authentication for the connection |
(Only displayed when Enable SASL is checked)
| Field | Default | Description |
|---|---|---|
| SASL Mechanism | PLAIN | Authentication mechanism: PLAIN, SCRAM-SHA-256, or SCRAM-SHA-512 |
| Username | - | SASL username for authentication |
| Password | - | SASL password. Masked on edit; leave empty to keep stored value |
- PLAIN: Simple username/password authentication. Use with TLS to protect credentials in transit.
- SCRAM-SHA-256: Challenge-response mechanism with SHA-256 hashing. More secure than PLAIN without requiring TLS.
- SCRAM-SHA-512: Same as SCRAM-SHA-256 but with stronger SHA-512 hashing.
4. TLS/Security Settings
| Field | Default | Description |
|---|---|---|
| Enable TLS | false | Enable TLS/SSL encryption for broker communication |
(Only displayed when Enable TLS is checked)
| Field | Default | Description |
|---|---|---|
| Skip Certificate Verification | false | Skip TLS certificate verification (not recommended for production) |
Enabling Skip Certificate Verification disables TLS certificate validation. Use only in trusted development environments, never in production.
5. Advanced Settings
| Field | Default | Description |
|---|---|---|
| Session Timeout | 10s | Timeout for detecting consumer failures, a duration from 1s to 300s. Should be at least 3x the heartbeat interval |
| Heartbeat Interval | 3s | Heartbeat frequency to the group coordinator, a duration from 500ms to 1m (e.g. 1500ms) |
| Acknowledgements | all | Who must acknowledge a record before a produce succeeds: all (every in-sync replica; the producer is idempotent), leader, or none. See Delivery guarantees |
| Delivery Timeout | 20s | How long the producer keeps retrying a record it could not deliver before the produce fails, a duration from 1s to 5m. A record already sent is never given up on mid-flight, so a failed produce was not written. Keep it below the produce node's timeout |
| Retry Backoff | 250ms | Pause between two retries within the delivery timeout, a duration from 0s to 1m |
6. Connection Labels
| Field | Default | Description |
|---|---|---|
| Labels | - | Key-value pairs to categorize and organize this Kafka connection (max 10 labels) |
Example Labels
env: prod: Environmentcluster: us-east-1: Cluster regionservice: streaming: Service role
- Required Fields: Profile Name and Brokers must be provided.
- Consumer Groups: Consumer group ID can be set at the connection level and optionally overridden per consume function. Consumers in the same group share topic partitions for load balancing.
- Session Timeout: If a consumer does not send a heartbeat within the session timeout, the broker considers it dead and rebalances. Set this to at least 3x the heartbeat interval.
- Retry Logic: A produce that fails (a broker restart, a leader election) is retried by the producer, Retry Backoff apart, until the delivery timeout. Max Retries is gone: a connection that still stores it keeps working, the value is no longer applied, and it is dropped the next time the connection is saved.
Delivery guarantees
What a Produce promises depends on Acknowledgements:
| Acknowledgements | Retries can duplicate a record | Order within a partition | An acknowledged record survives the leader failing |
|---|---|---|---|
all (default) | No: the producer is idempotent, and the broker drops a retried batch it already wrote | Kept, retries included (up to 5 requests in flight) | Yes, when the topic has replication factor 2 or more and min.insync.replicas 2 or more |
leader | Yes | Kept (one request in flight) | No: a record the leader acknowledged and had not replicated is lost |
none | Yes | Kept (one request in flight) | No acknowledgement at all: a record the broker never received is lost without an error, and the produce reports offset -1 (unknown) |
min.insync.replicas is a topic (or broker) setting. With min.insync.replicas=1, all can still be acknowledged by the leader alone, so set it to 2 on topics whose records must survive a broker failure.
A produce that fails was not written. The producer retries a record for up to the delivery timeout, and gives up on it only when that is safe: the record was never sent, or the broker answered. A record already sent whose answer was lost is never abandoned; the produce waits for its outcome. So when the node keeps a failed write for later delivery (store-and-forward), the later delivery is not a duplicate.
What idempotence does not cover. A produce that is run again after its record was written, without the first run learning so, is a new send the broker cannot recognise: the node stopped waiting for a record still being delivered (keep the delivery timeout below the node's timeout), or MaestroHub restarted with a record in flight. Delivery is at-least-once across those. The message key only chooses the partition: Kafka does not deduplicate by key. Consumers that must not see a record twice should deduplicate on an id in the payload. Exactly-once delivery would need a transactional producer, which the connector does not offer.
On Kafka versions before 3.0, the idempotent producer needs the IdempotentWrite permission on the cluster. If the connection's principal lacks it, the first produce fails with a cluster authorization error that says so, and is not retried. Grant the permission, or set Acknowledgements to leader.
Function Builder
Creating Kafka Functions
Once you have a connection established, you can create reusable produce and consume functions:
- Open the connection and go to its Functions tab → New Function
- Select the desired function type (Produce or Consume)
- Configure the function parameters
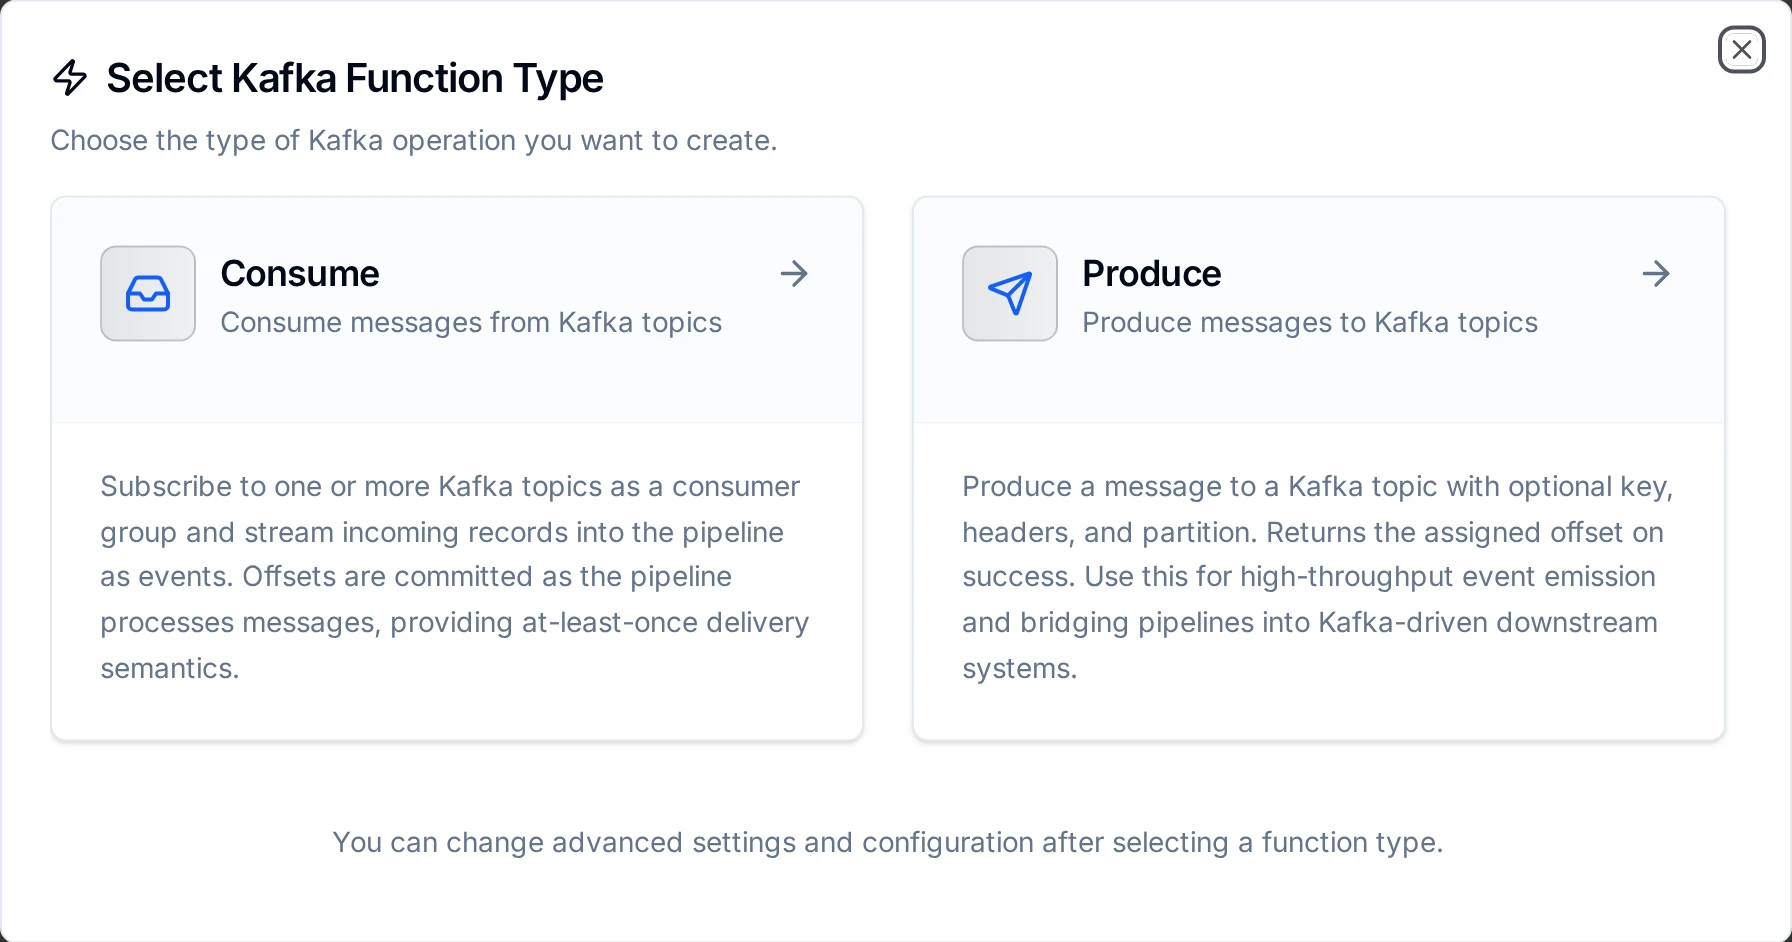
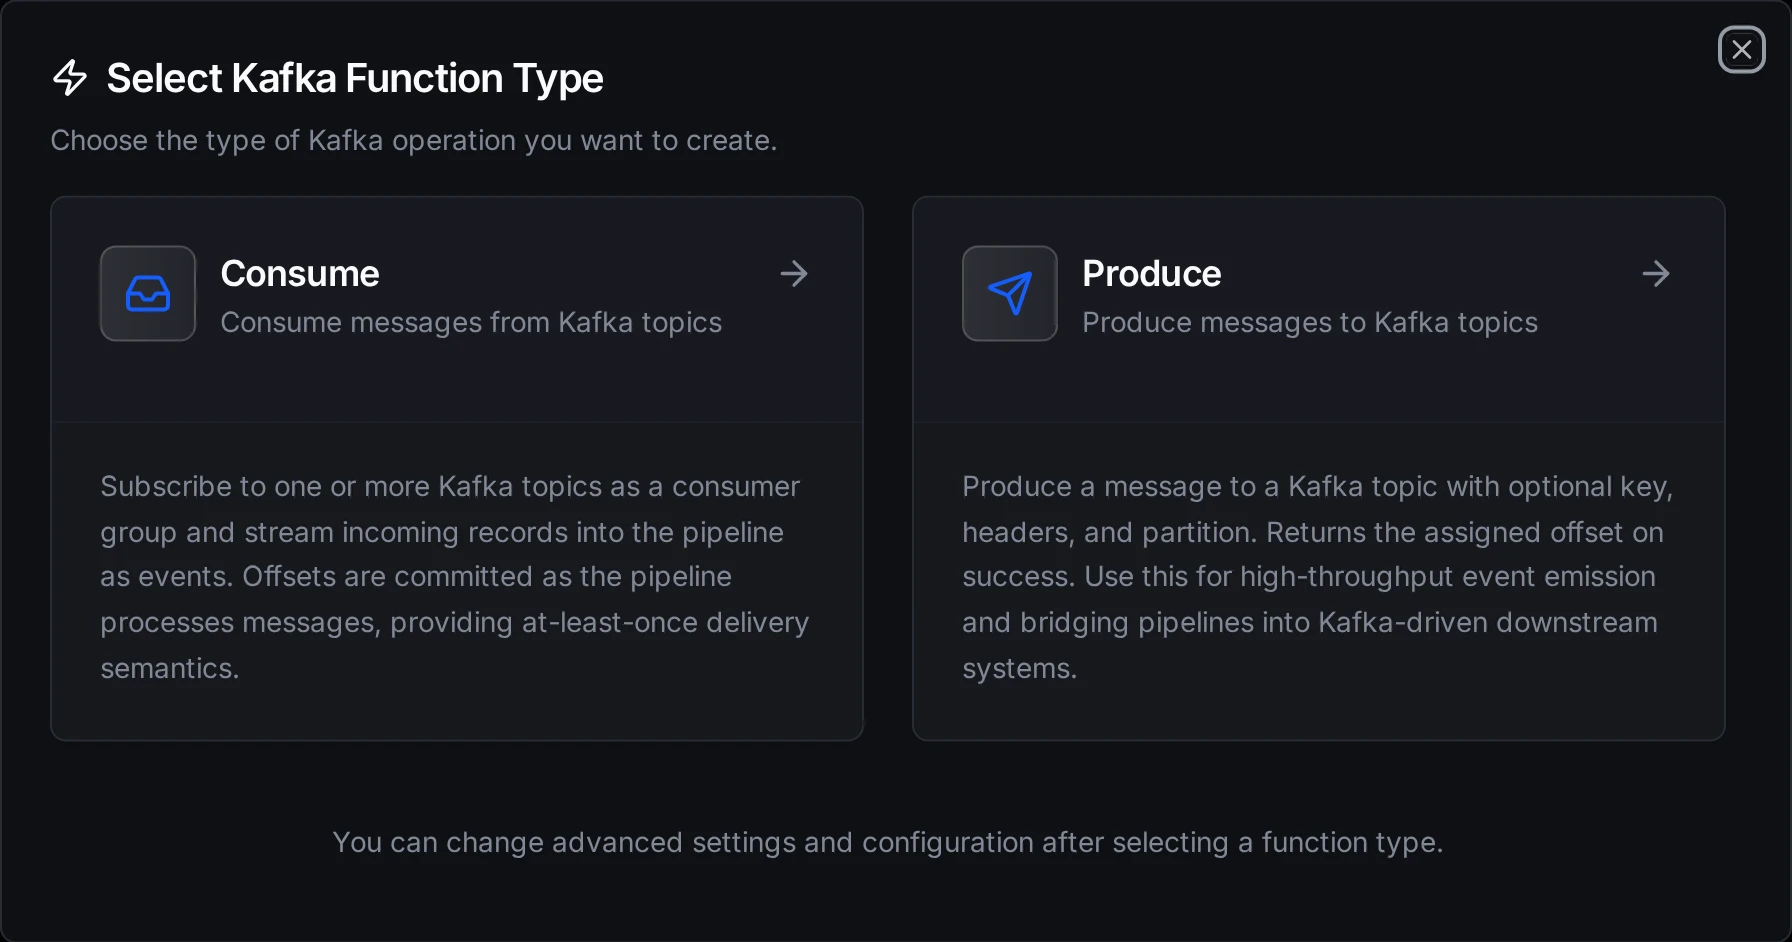
Select from two Kafka function types: Produce for sending messages and Consume for receiving messages
Produce Function
Purpose: Produce messages to Kafka topics with key-based partitioning, custom headers, and dynamic payloads. Use this for event streaming, data ingestion, and inter-service messaging.
Configuration Fields
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| Topic | String | Yes | - | Kafka topic to produce messages to. Supports template parameters. |
| Key | String | No | - | Message key for topic partitioning. Messages with the same key are sent to the same partition. Supports template parameters. |
| Payload | String | Yes | - | Message payload content (JSON or text). Supports template parameters. |
| Headers | JSON | No | - | Custom message headers for metadata propagation (e.g., {"source": "iot-gateway", "version": "1.0"}). Supports template parameters. |
| Partition | Number | No | auto | Target partition number (0+). Leave empty for automatic partitioning based on message key. |
Example Configuration
// Topic
sensor-events

// Key (for partitioning by device)
((deviceId))

// Payload
{
  "temperature": ((temperature)),
  "humidity": ((humidity)),
  "timestamp": "((timestamp))",
  "source": "((deviceId))"
}

// Headers
{"source": "iot-gateway", "contentType": "application/json"}
Use Cases:
- Stream sensor events to downstream consumers
- Forward logs and audit events for centralized processing
- Ingest real-time data into analytics pipelines
- Publish commands and events for microservice architectures
Consume Function
Purpose: Consume messages from Kafka topics using consumer groups for load balancing and fault tolerance. Subscribe functions are used as pipeline triggers to start execution when messages arrive.
Configuration Fields
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| Topic | String | Yes | - | Kafka topic to consume messages from. |
| Consumer Group | String | No | Connection default | Override the consumer group ID from connection settings. Leave empty to use the connection-level consumer group. |
| Start Position | Choice | No | Latest | Where to begin on a partition this consumer group has no committed offset for: Latest (only messages produced from now on) or Earliest (the oldest message the topic still holds). |
Example Configuration
// Topic
sensor-events

// Consumer Group
sensor-processing-group

// Start Position
Latest
- At-least-once. A message's offset is committed once MaestroHub has durably stored it for the pipeline. If MaestroHub cannot store it, the trigger retries that message before reading anything after it on the same partition, so nothing is skipped.
- Resuming. The first time the consumer group reads a partition, the trigger commits its start offset straight away. Disabling and enabling the pipeline later resumes from the committed offset on every partition, so messages produced while it was disabled are delivered.
- Start Position only applies with no committed offset: a new consumer group, or one whose committed offsets the broker has expired. Kafka removes a group's committed offsets after the group has been inactive for the broker's
offsets.retention.minutes(7 days by default); a pipeline disabled for longer starts again from its Start Position. Each time that happens, MaestroHub logs a warning naming the partition and the offset it started from.
Use Cases:
- Trigger pipelines on incoming stream events
- Process event-driven microservice messages
- Ingest real-time analytics data
- Handle change data capture (CDC) events
Using Parameters
The ((parameterName)) syntax creates dynamic, reusable functions. Parameters are automatically detected from your configuration fields and can be configured with:
| Configuration | Description | Example |
|---|---|---|
| Type | Data type validation | string, number, boolean, datetime, json, buffer |
| Required | Make parameters mandatory or optional | Required / Optional |
| Default Value | Fallback value if not provided | sensor-events, 0, {} |
| Description | Help text for users | "Target topic name", "Device identifier" |
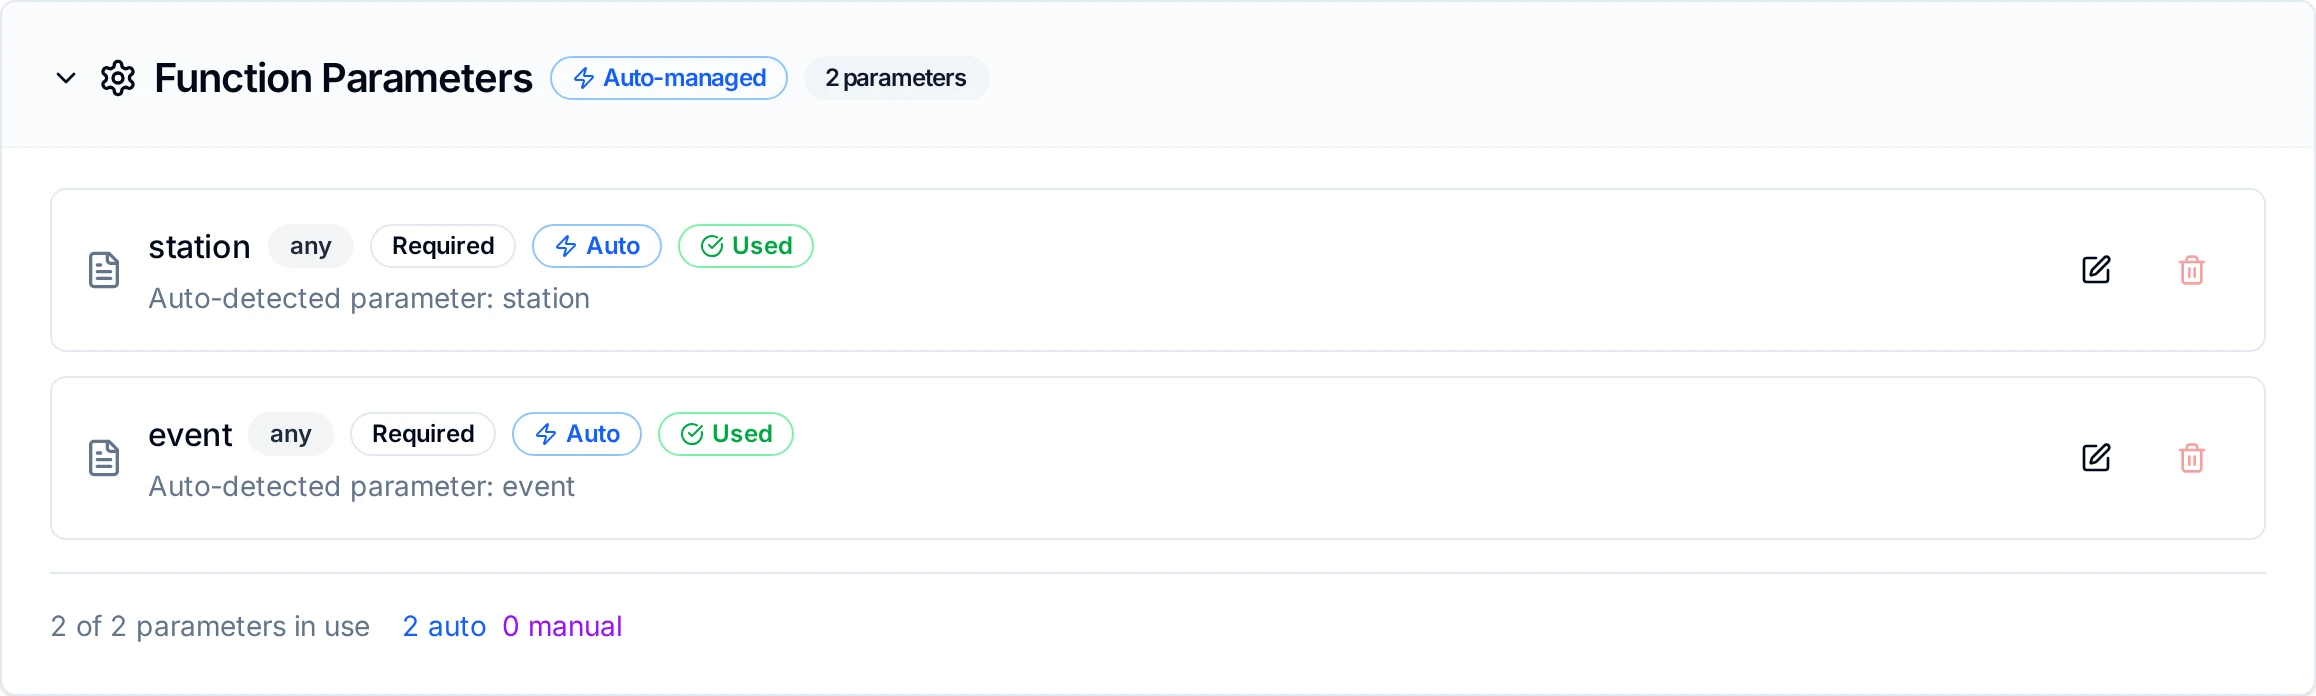
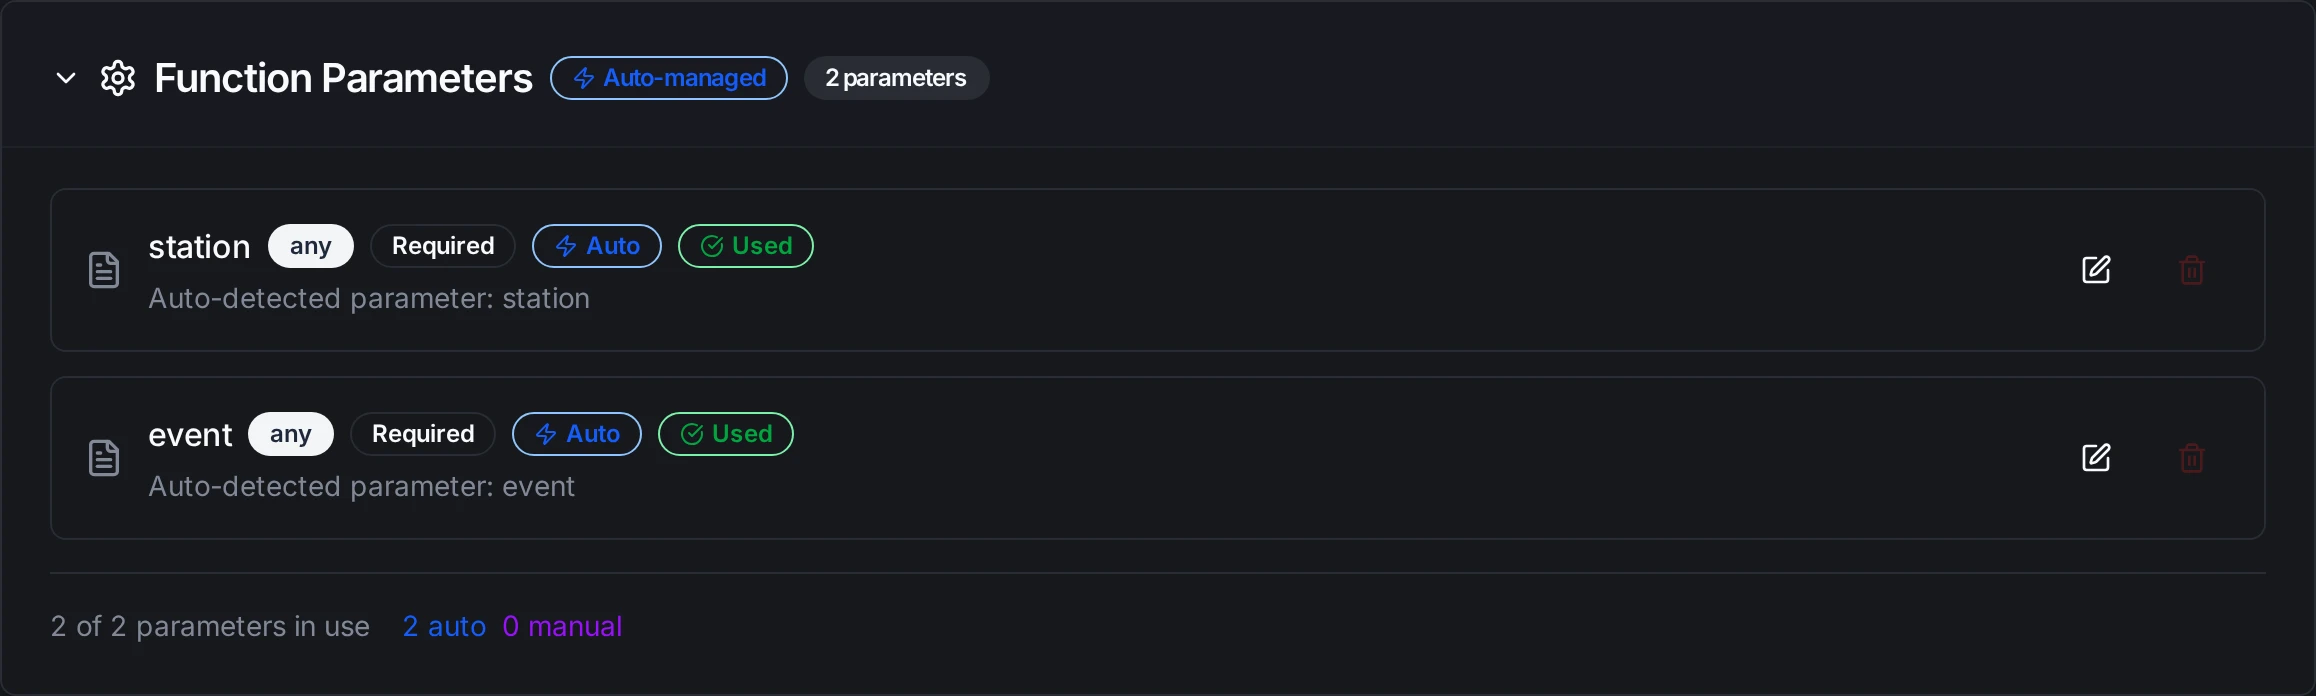
Configure dynamic parameters for Kafka functions with type validation, defaults, and descriptions
Template parameters are available for Produce functions (in topic, key, payload, and headers). Consume functions are event-driven triggers and do not accept runtime parameters.
Pipeline Integration
Use the Kafka functions you create here as nodes inside the Pipeline Designer. Drag the function node onto the canvas, bind its parameters to upstream outputs or constants, and configure error handling as needed.
Common patterns include:
- Collect → Stream: Gather data from OPC UA, Modbus, or MQTT and produce to Kafka topics
- Consume → Process → Produce: Read from one topic, transform data, and write to another
- Consume → Store: Ingest Kafka messages and write to MongoDB, PostgreSQL, or InfluxDB
- Consume → Alert: React to stream events and trigger notifications via SMTP or MS Teams
For broader orchestration patterns that combine Kafka with SQL, REST, MQTT, or other connector steps, see the Nodes page.
Common Use Cases
IoT Event Streaming
Scenario: Collect sensor readings from factory equipment and stream them to Kafka for distributed processing by multiple consumer applications.
Produce Configuration:
- Topic:
factory-telemetry - Key:
((machineId)) - Payload:
{
  "machineId": "((machineId))",
  "temperature": ((temperature)),
  "vibration": ((vibration)),
  "timestamp": "((timestamp))"
}
- Headers:
{"plant": "chicago", "line": "assembly-1"}
Pipeline Integration: Connect after OPC UA or Modbus read nodes to continuously stream equipment telemetry into Kafka.
Real-Time Log Aggregation
Scenario: Forward application and system logs to a centralized Kafka topic for aggregation, search, and analysis.
Produce Configuration:
- Topic:
logs-((service)) - Key:
((hostname)) - Payload:
{
  "level": "((level))",
  "message": "((message))",
  "service": "((service))",
  "timestamp": "((timestamp))"
}
Pipeline Integration: Use with REST webhook triggers to capture log events and forward them to Kafka for downstream consumers like Elasticsearch or Splunk.
Stream Processing Pipeline
Scenario: Consume raw sensor events from Kafka, apply transformations and enrichment, and produce processed results to a new topic.
Consume Configuration:
- Topic:
raw-sensor-events - Consumer Group:
sensor-enrichment - Start Position: Latest
Produce Configuration (downstream):
- Topic:
enriched-sensor-events - Key:
((sensorId)) - Payload: Transformed data from upstream processing
Pipeline Integration: Chain a Kafka consume trigger with transform nodes and a Kafka produce node to build a complete stream processing pipeline.
Event-Driven Notifications
Scenario: Consume alert events from Kafka and route them to appropriate notification channels based on severity.
Consume Configuration:
- Topic:
alerts - Consumer Group:
alert-routing - Start Position: Latest
Pipeline Integration: Connect to condition nodes that route by severity level: critical alerts to MS Teams, warnings to SMTP email, and informational events to MongoDB for audit logging.